X · @AnthropicAI / 长帖
Claude 写了 413 份笔记,只拿到 1 枚徽章:智能体记忆该怎么整理
413 份笔记只换来 1 枚徽章,10 份笔记却拿到 4 枚。Anthropic 用宝可梦、数据库与法律文档实验,拆解智能体怎样筛选经验、核对错误,并让下一次任务用上记忆。
乔木改写
同样玩《宝可梦 红》,Claude Sonnet 3.7 写了 413 份记忆文件,拿到 1 枚徽章。Claude Fable 5 只留下 10 份文件,拿到 4 枚。
Anthropic 对比的是两个模型各一次运行、约进行到 10,000 步时的情况。这个对照无法单独证明文件越少越好,但它暴露了一个具体问题:记下的东西越多,智能体可能越忙着整理过去,越顾不上正在做的事。
Sonnet 3.7 开始创建第四个“主记忆”文件夹后,接下来 17 步都在整理文件。它新建 6 份,删除 9 份,游戏一步没动。
怎样让智能体留下真正有用的经验,还能纠正已经记错的内容?Anthropic 在 2026 年 11 月 6 日发布的《The components of agent memory》中,介绍了他们对记忆系统的拆解,以及一套叫作 dreaming 的整理过程。
智能体空闲时,可以回头核对自己记了什么
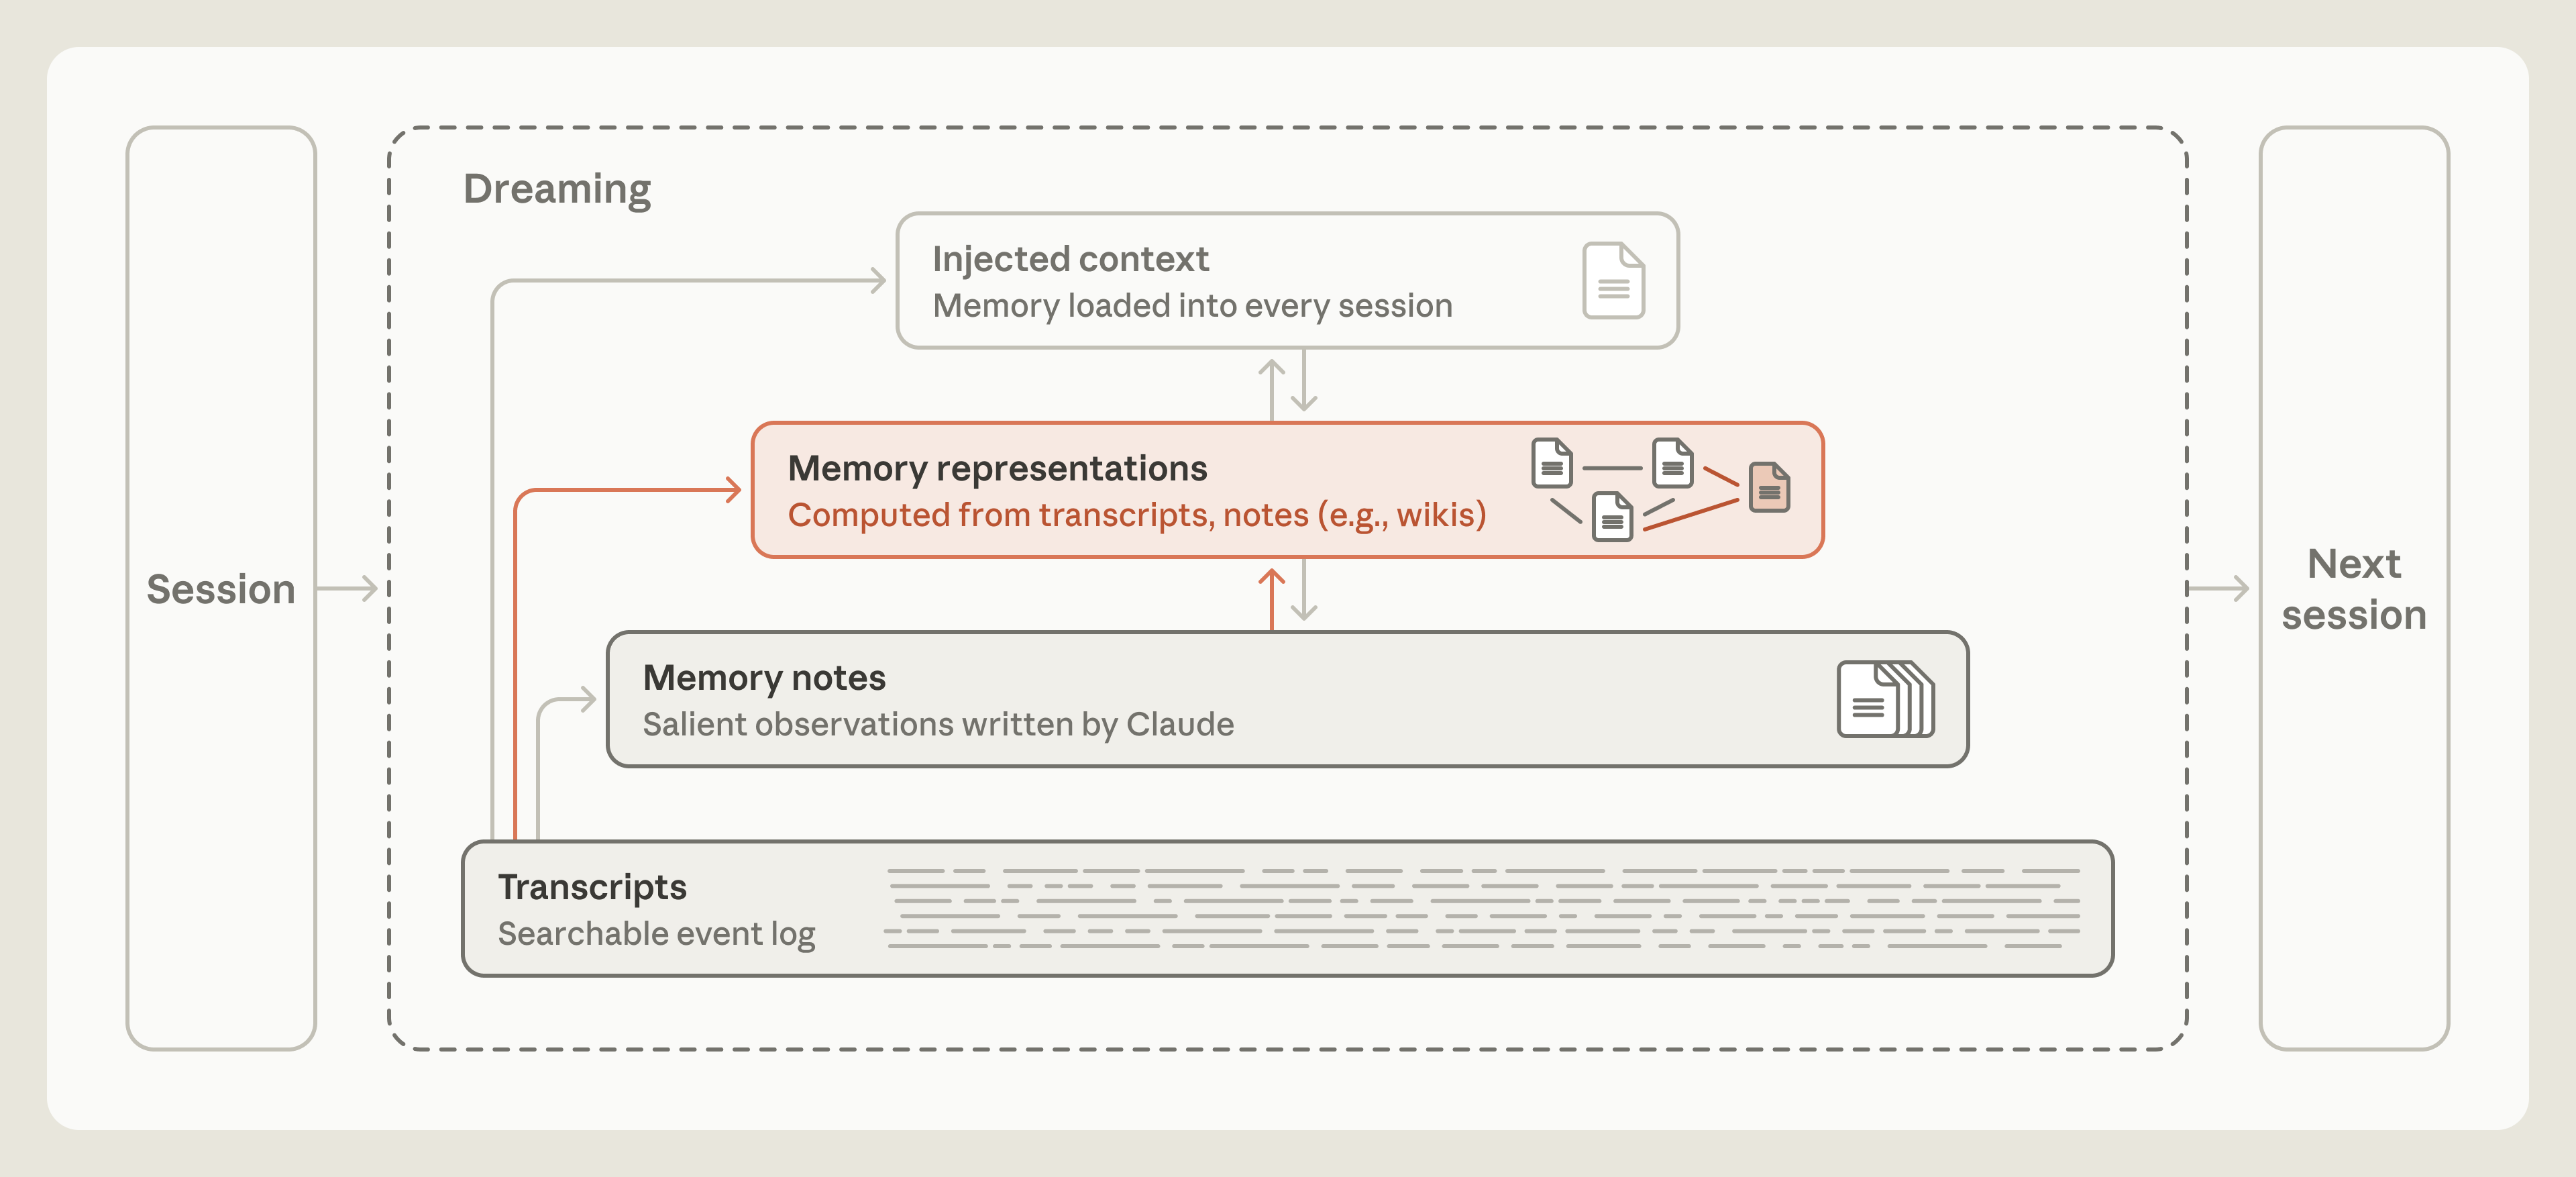
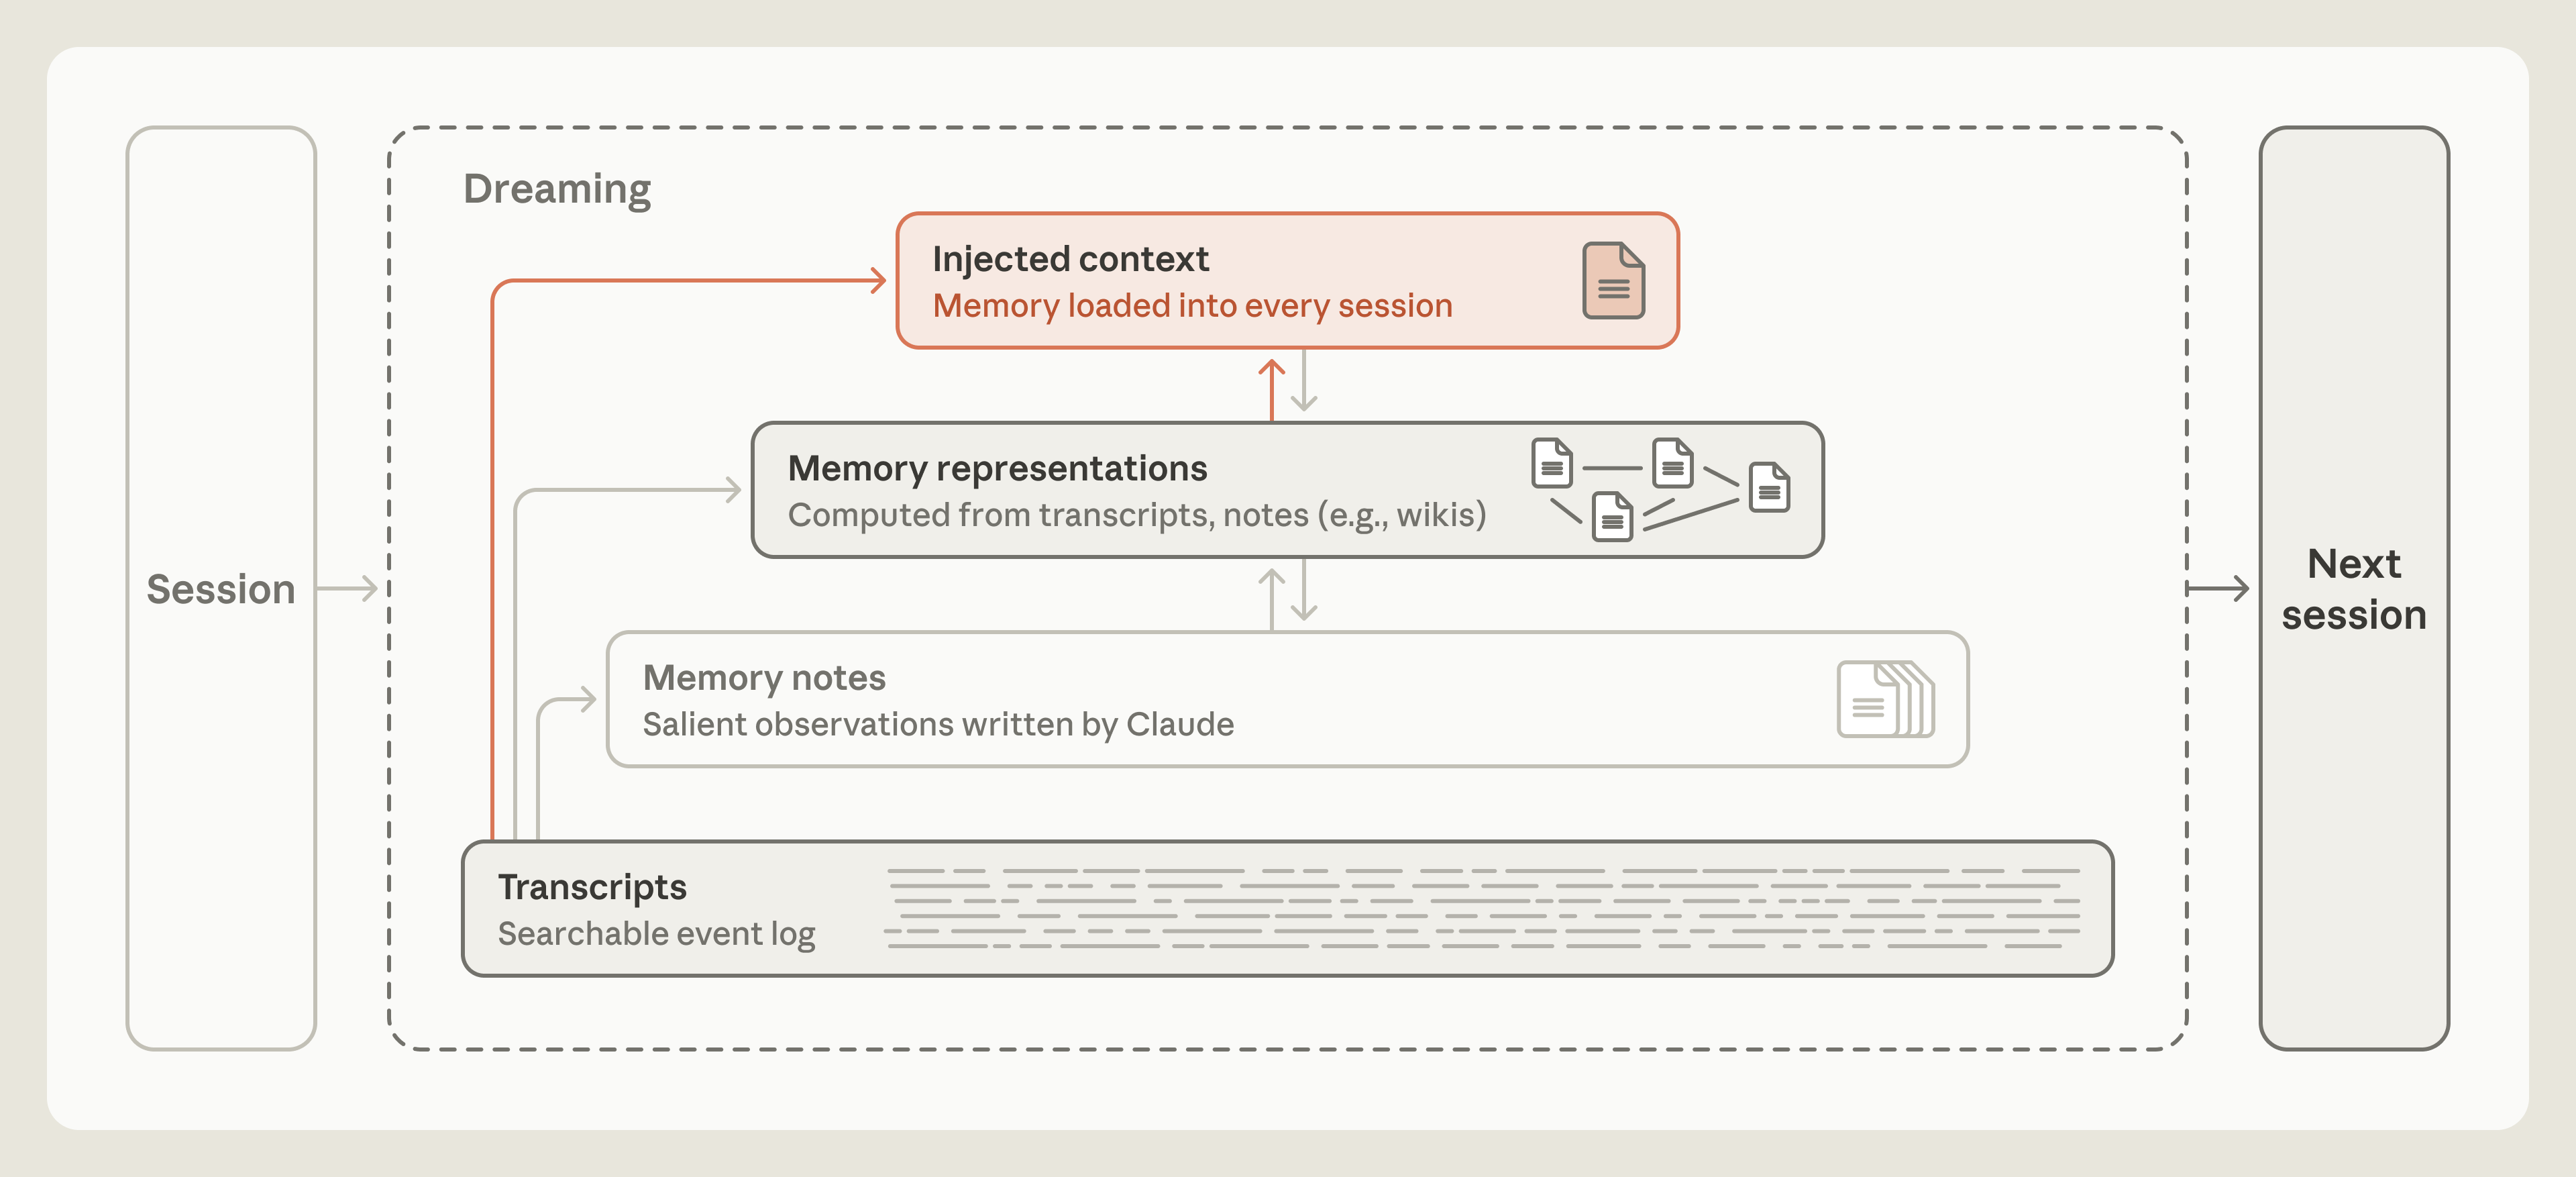
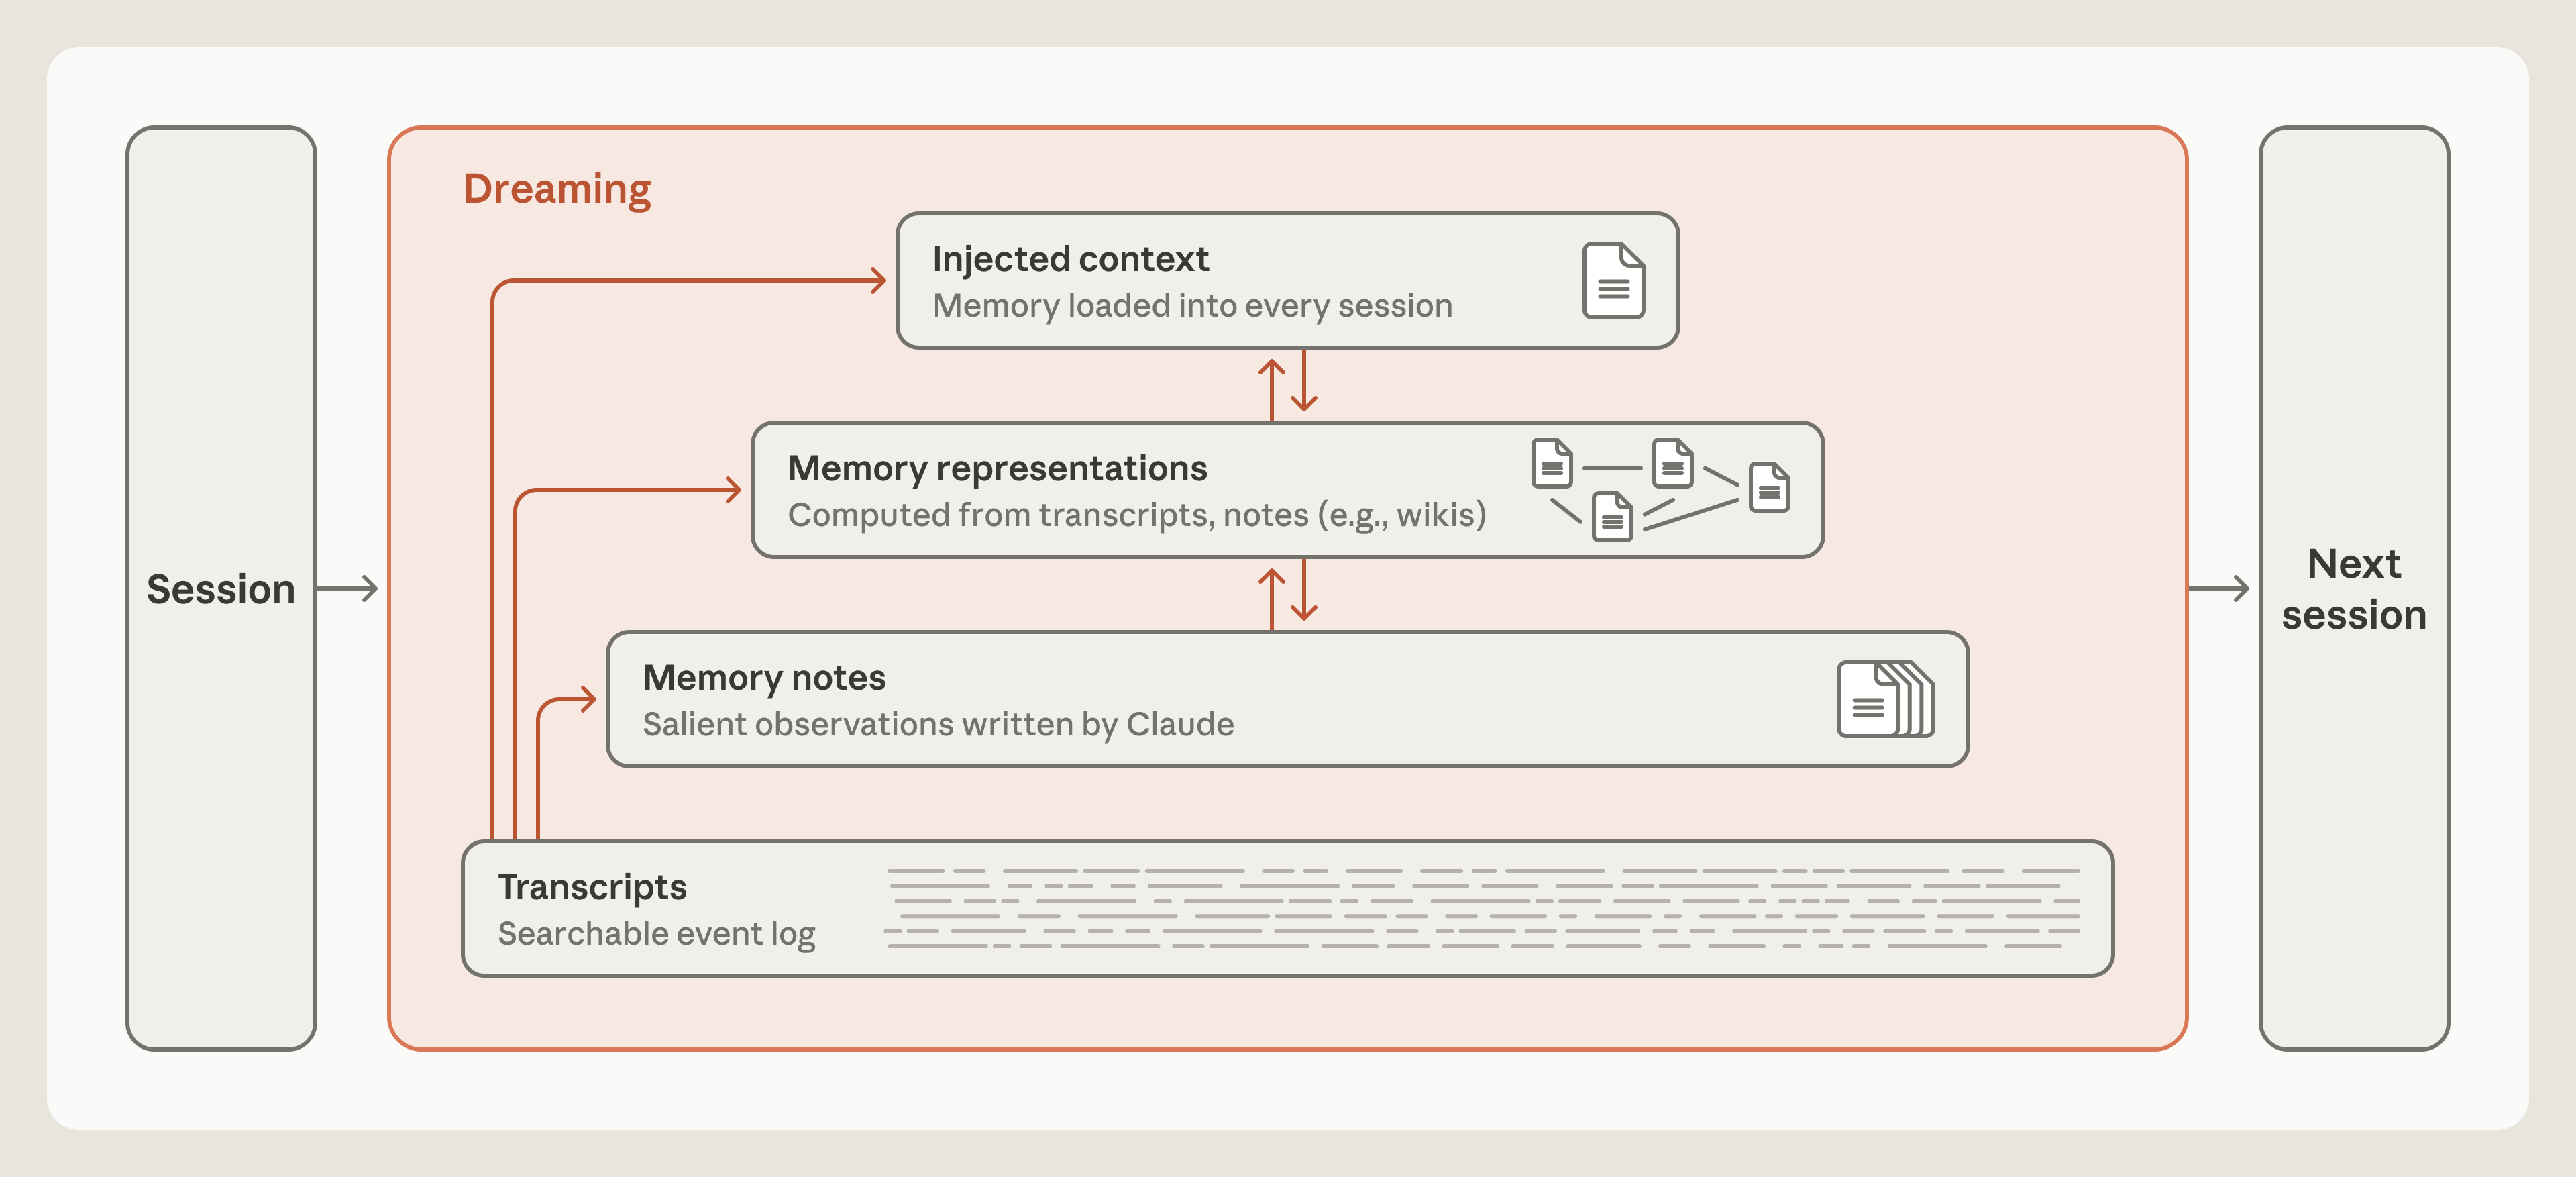
Dreaming 可以理解为智能体利用会话之间的空闲时间,重新检查日志、修正笔记、整理知识,以及挑出下次会话应该提前读到的内容。
这套思路借鉴了人类记忆的分工。海马体先捕获当下的体验,睡眠和安静休息期间的重放,再帮助其中一部分体验逐渐整合成长时知识。Letta 与加州大学伯克利分校的研究者此前提出过“睡眠时计算”,让模型在交互间隙重组已有上下文。
智能体也会留下大量工作日志。任务进行时,它可以先记录重要线索;任务暂停后,再回头检查这些线索是否正确、是否值得长期保留。
媒体未能载入,请通过下方原文链接查看。
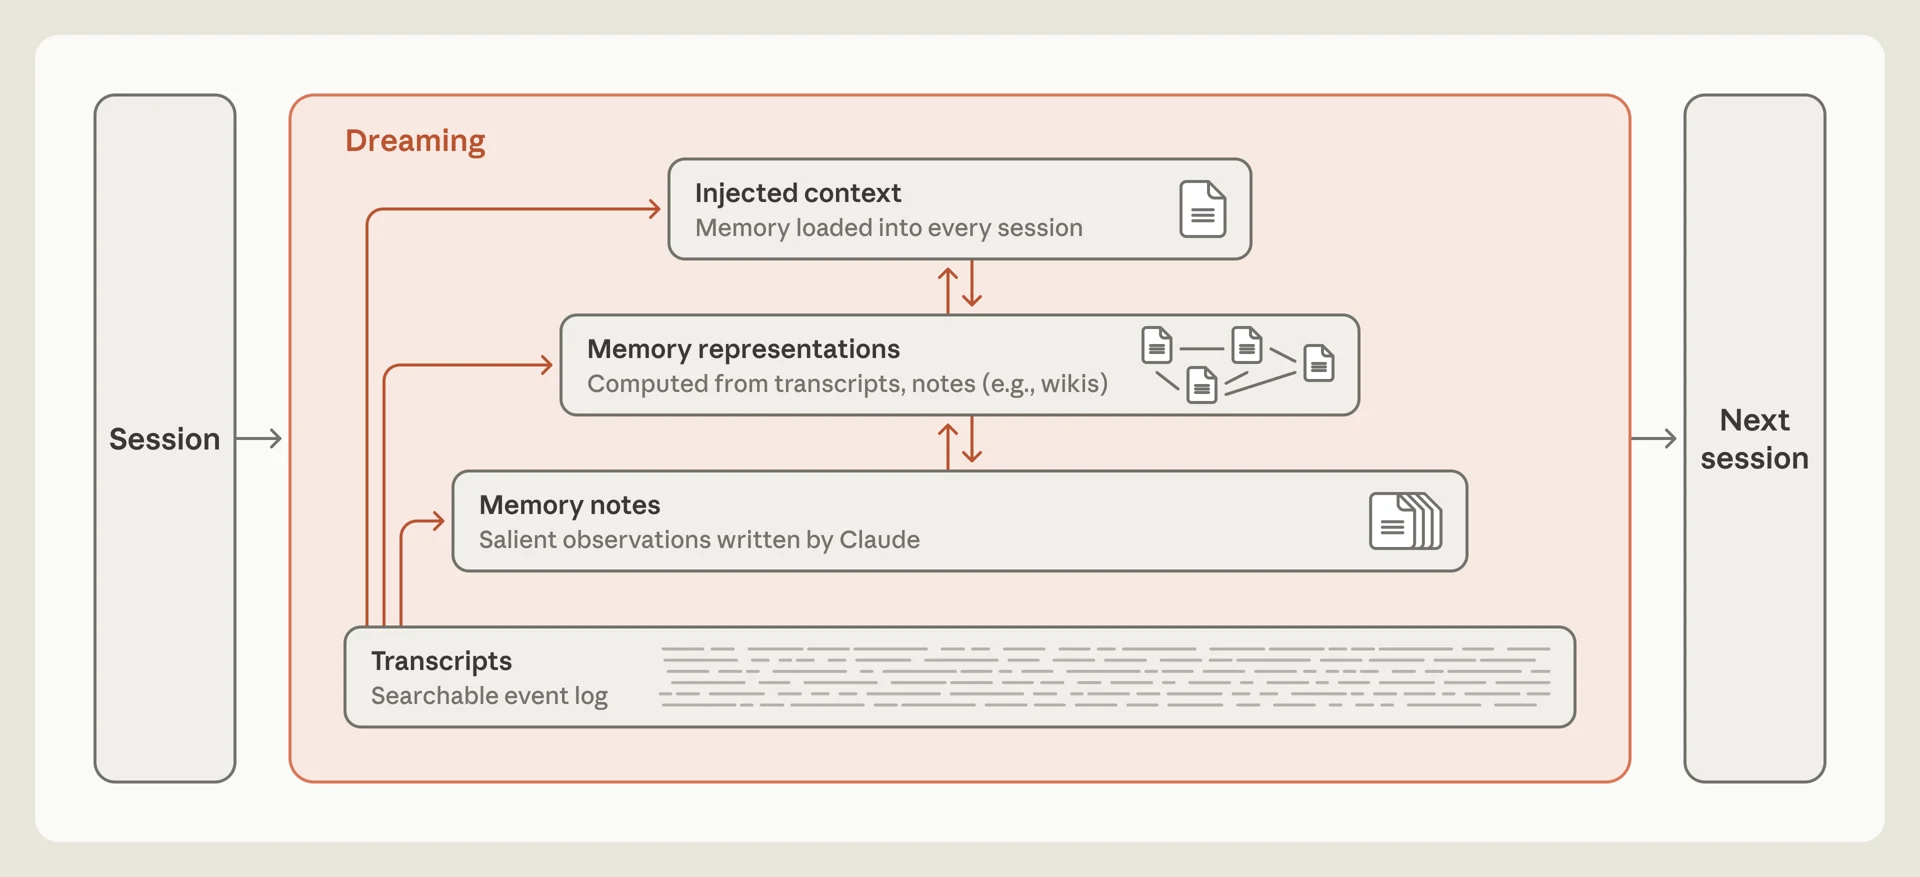
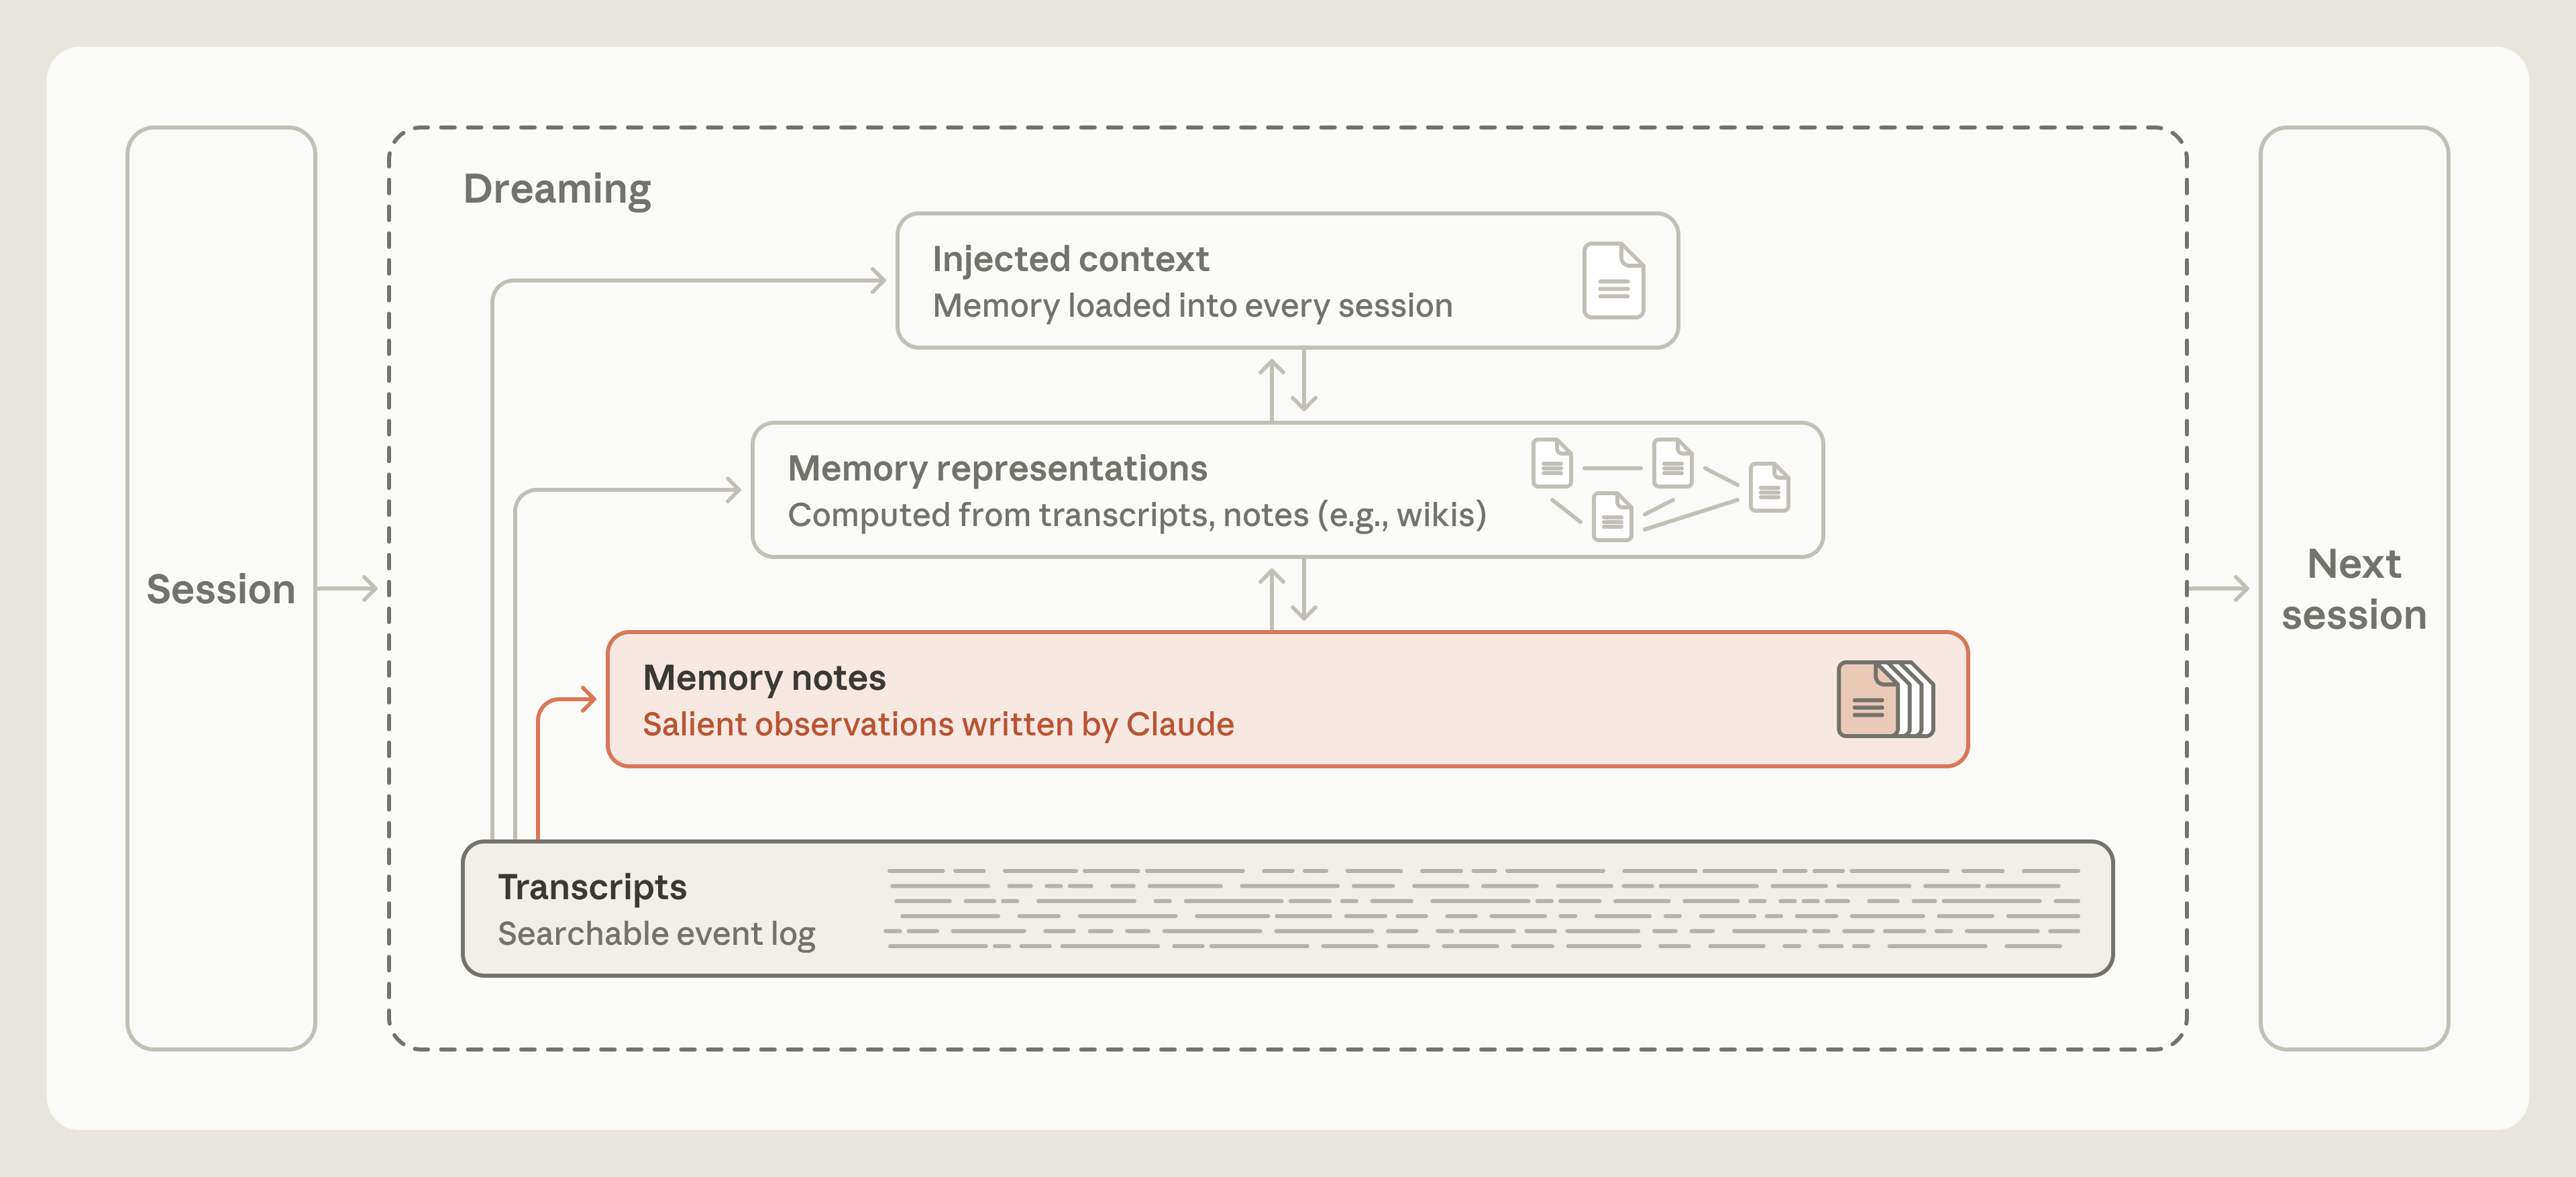
图 1:从原始会话日志,到记忆笔记、知识库,再到每次会话预先载入的上下文。Dreaming 可以在这些层级之间整理信息。
文章里的“记忆”有明确边界:Claude 从任务或用户互动中得到经验,把经验保存下来,供之后的会话重新读取。修改模型权重、单次对话内的学习,以及为延续上下文而做的对话压缩,都不在这次讨论范围内。
Claude 可以给日志中的重要事件打标签,也可以把观察写进记忆文件夹。难处在于,写下笔记的那一刻,它还不知道下一次任务会问什么。
媒体未能载入,请通过下方原文链接查看。
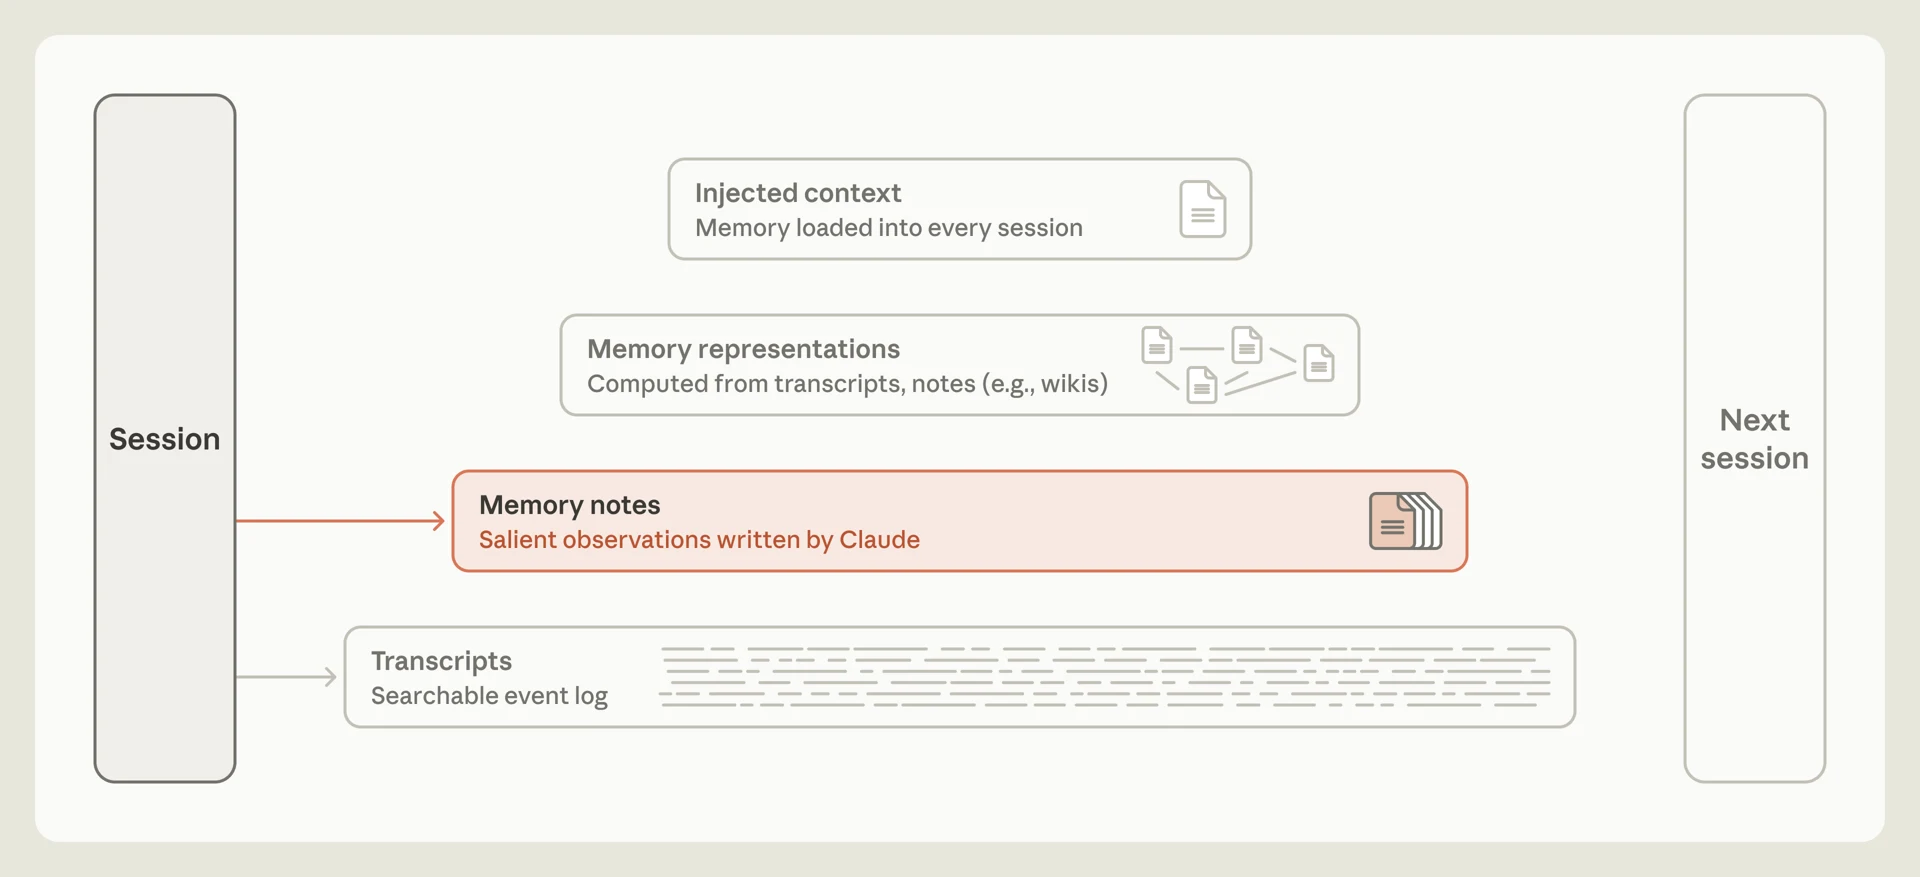
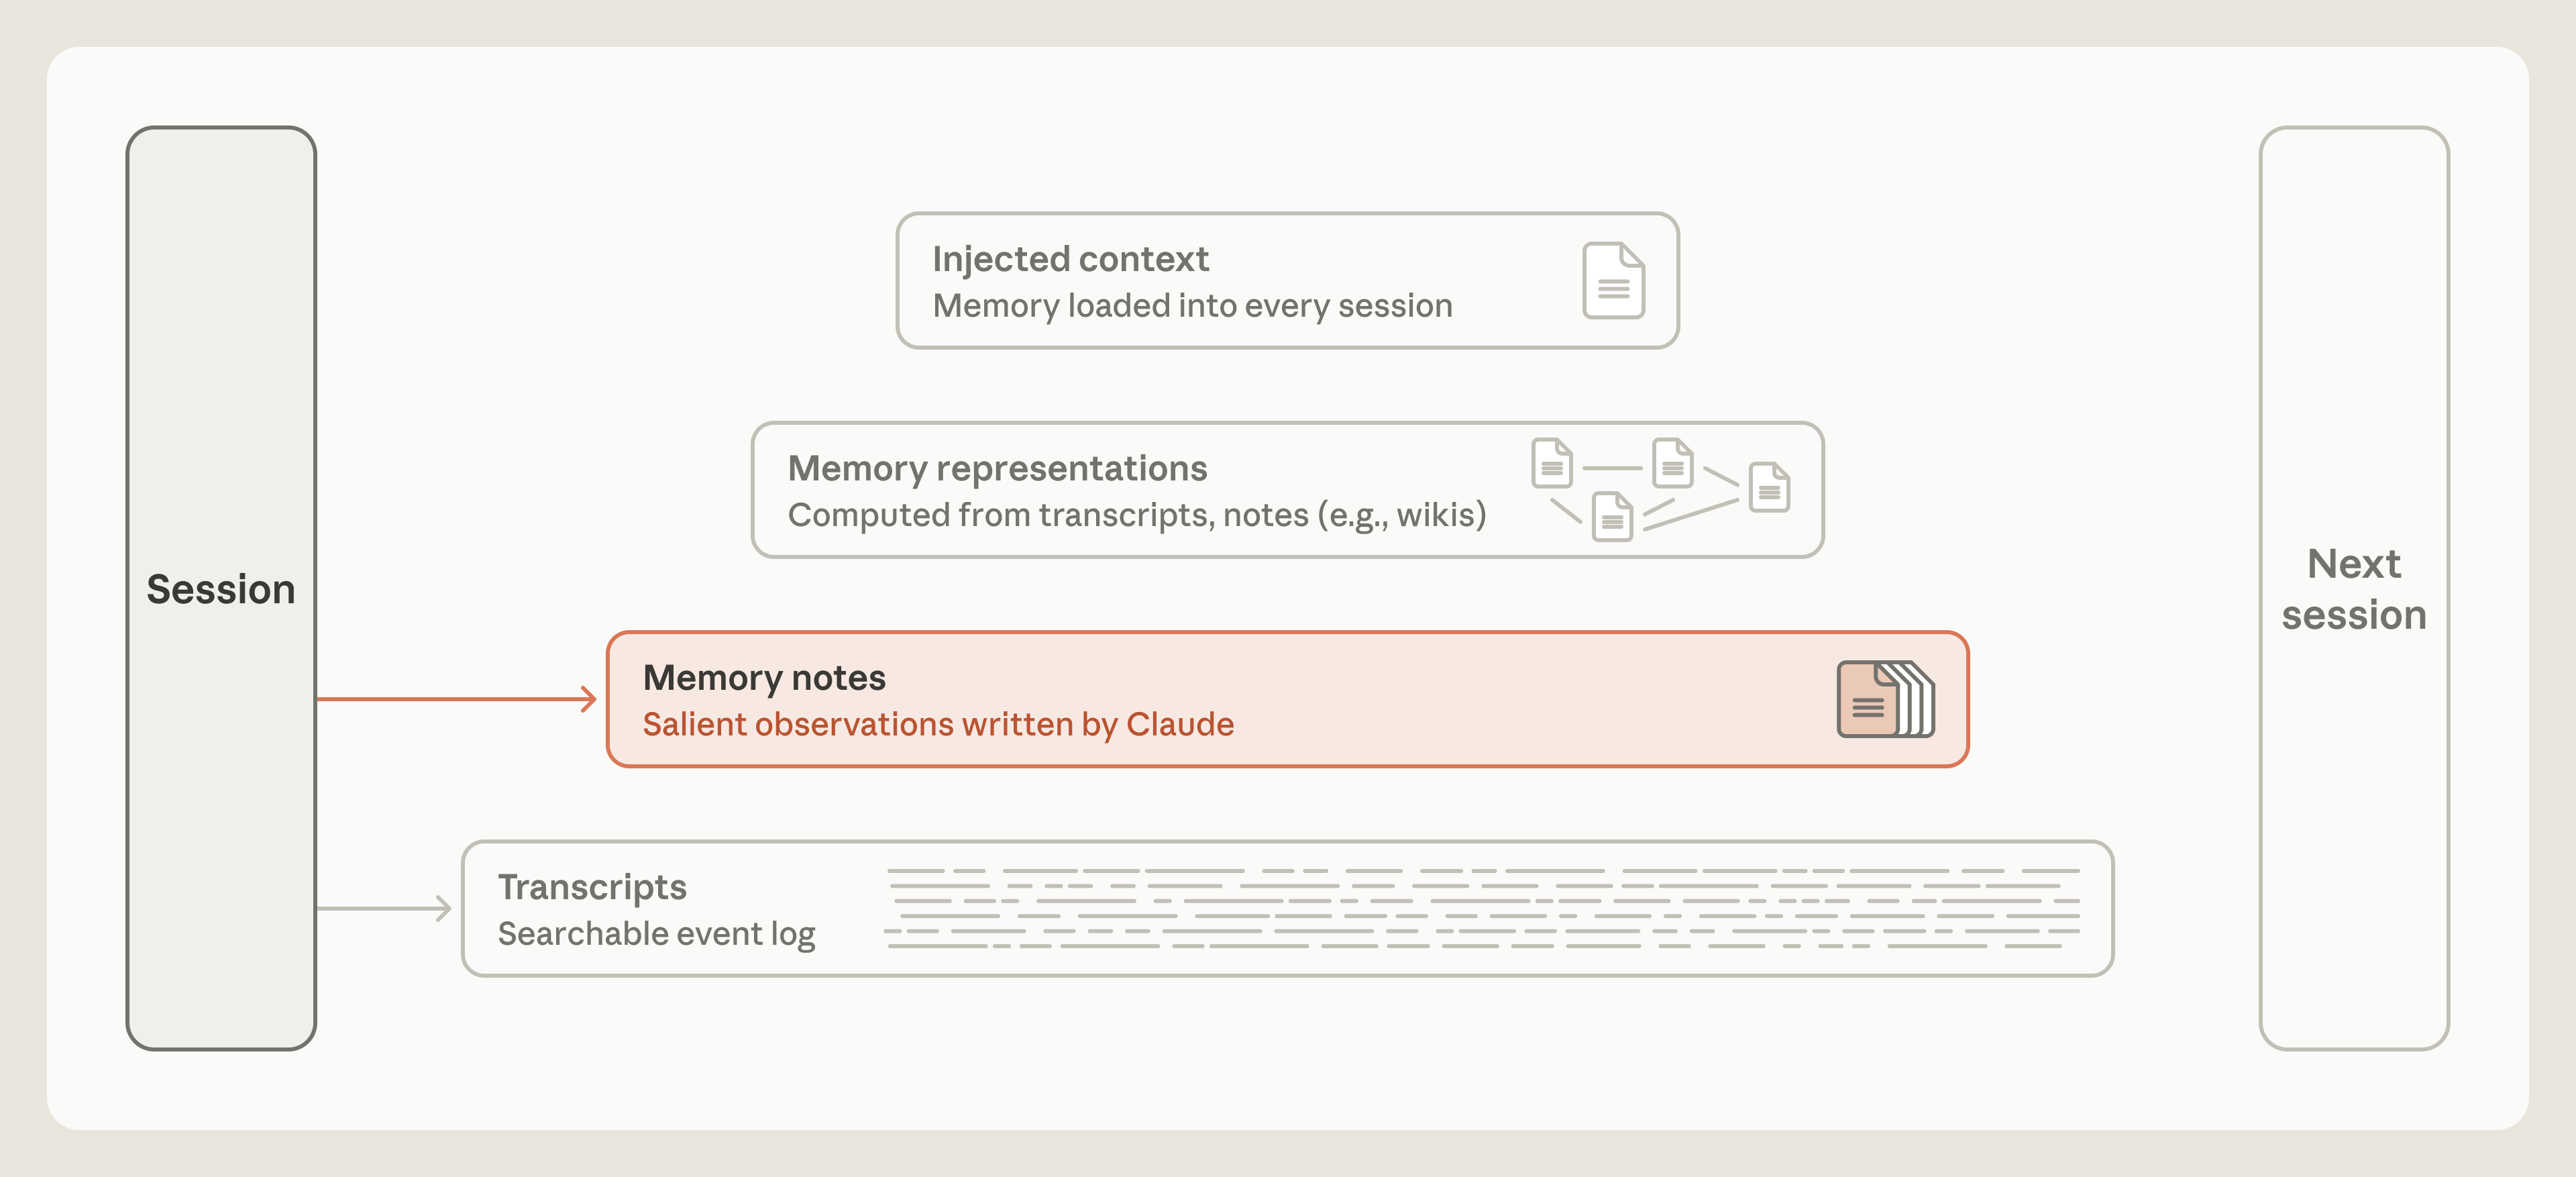
图 2:Claude 在会话中挑出值得保留的观察,写入跨会话保存的记忆笔记。
有用的笔记,要把猜测变成验证过的规则
写下一条规则,实际上是在预测:未来还会遇到类似情形。若笔记里只剩未经检验的猜测,下一次读取它时,模型就可能把旧猜测当成已知事实。
Anthropic 用 CL-Bench 1.0 的数据库任务观察这个过程。Claude 需要查询数据库,逐题回答问题。每次作答后,系统给出正确答案;模型可以复盘错误、提出解释、验证解释,再把结果写入记忆。
每道题都从全新会话开始,只有记忆目录会保留下来。这让评测能够观察跨会话记忆带来的变化。
不同模型写下的东西差别很大。Sonnet 4.6 留下不少分散文件,里面是答错原因的猜测,但缺少验证。Opus 4.7 开始把笔记整理成参考文档,区分已核实与未确认的内容。Sonnet 5 会在评分器确认后标注答案,答错时补上纠正。
Opus 5 是这批模型中第一个把这个过程接完整的:记录规则,同时写清依据、以前的答案,以及途中发现的陷阱。Opus 5.5 和 Sonnet 5.5 也能保存经过验证、供后续作答使用的规则。
媒体未能载入,请通过下方原文链接查看。
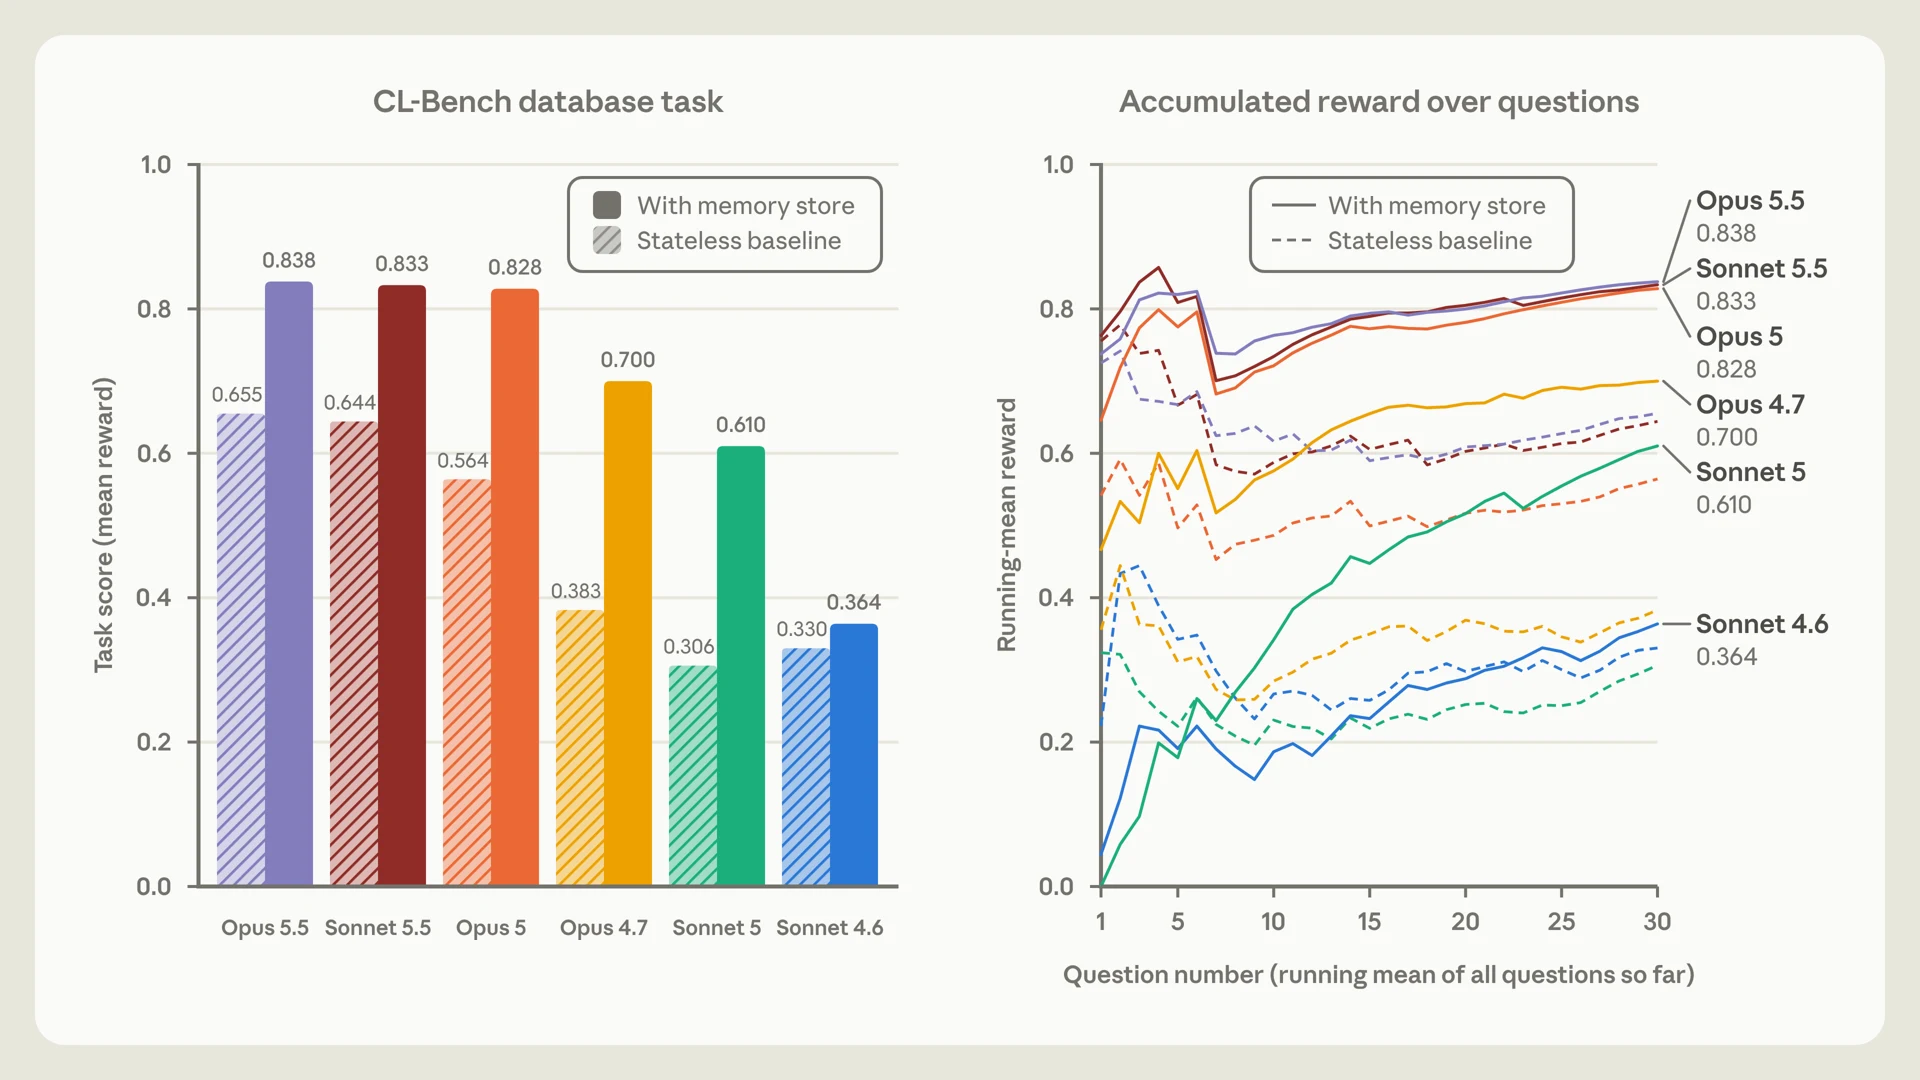
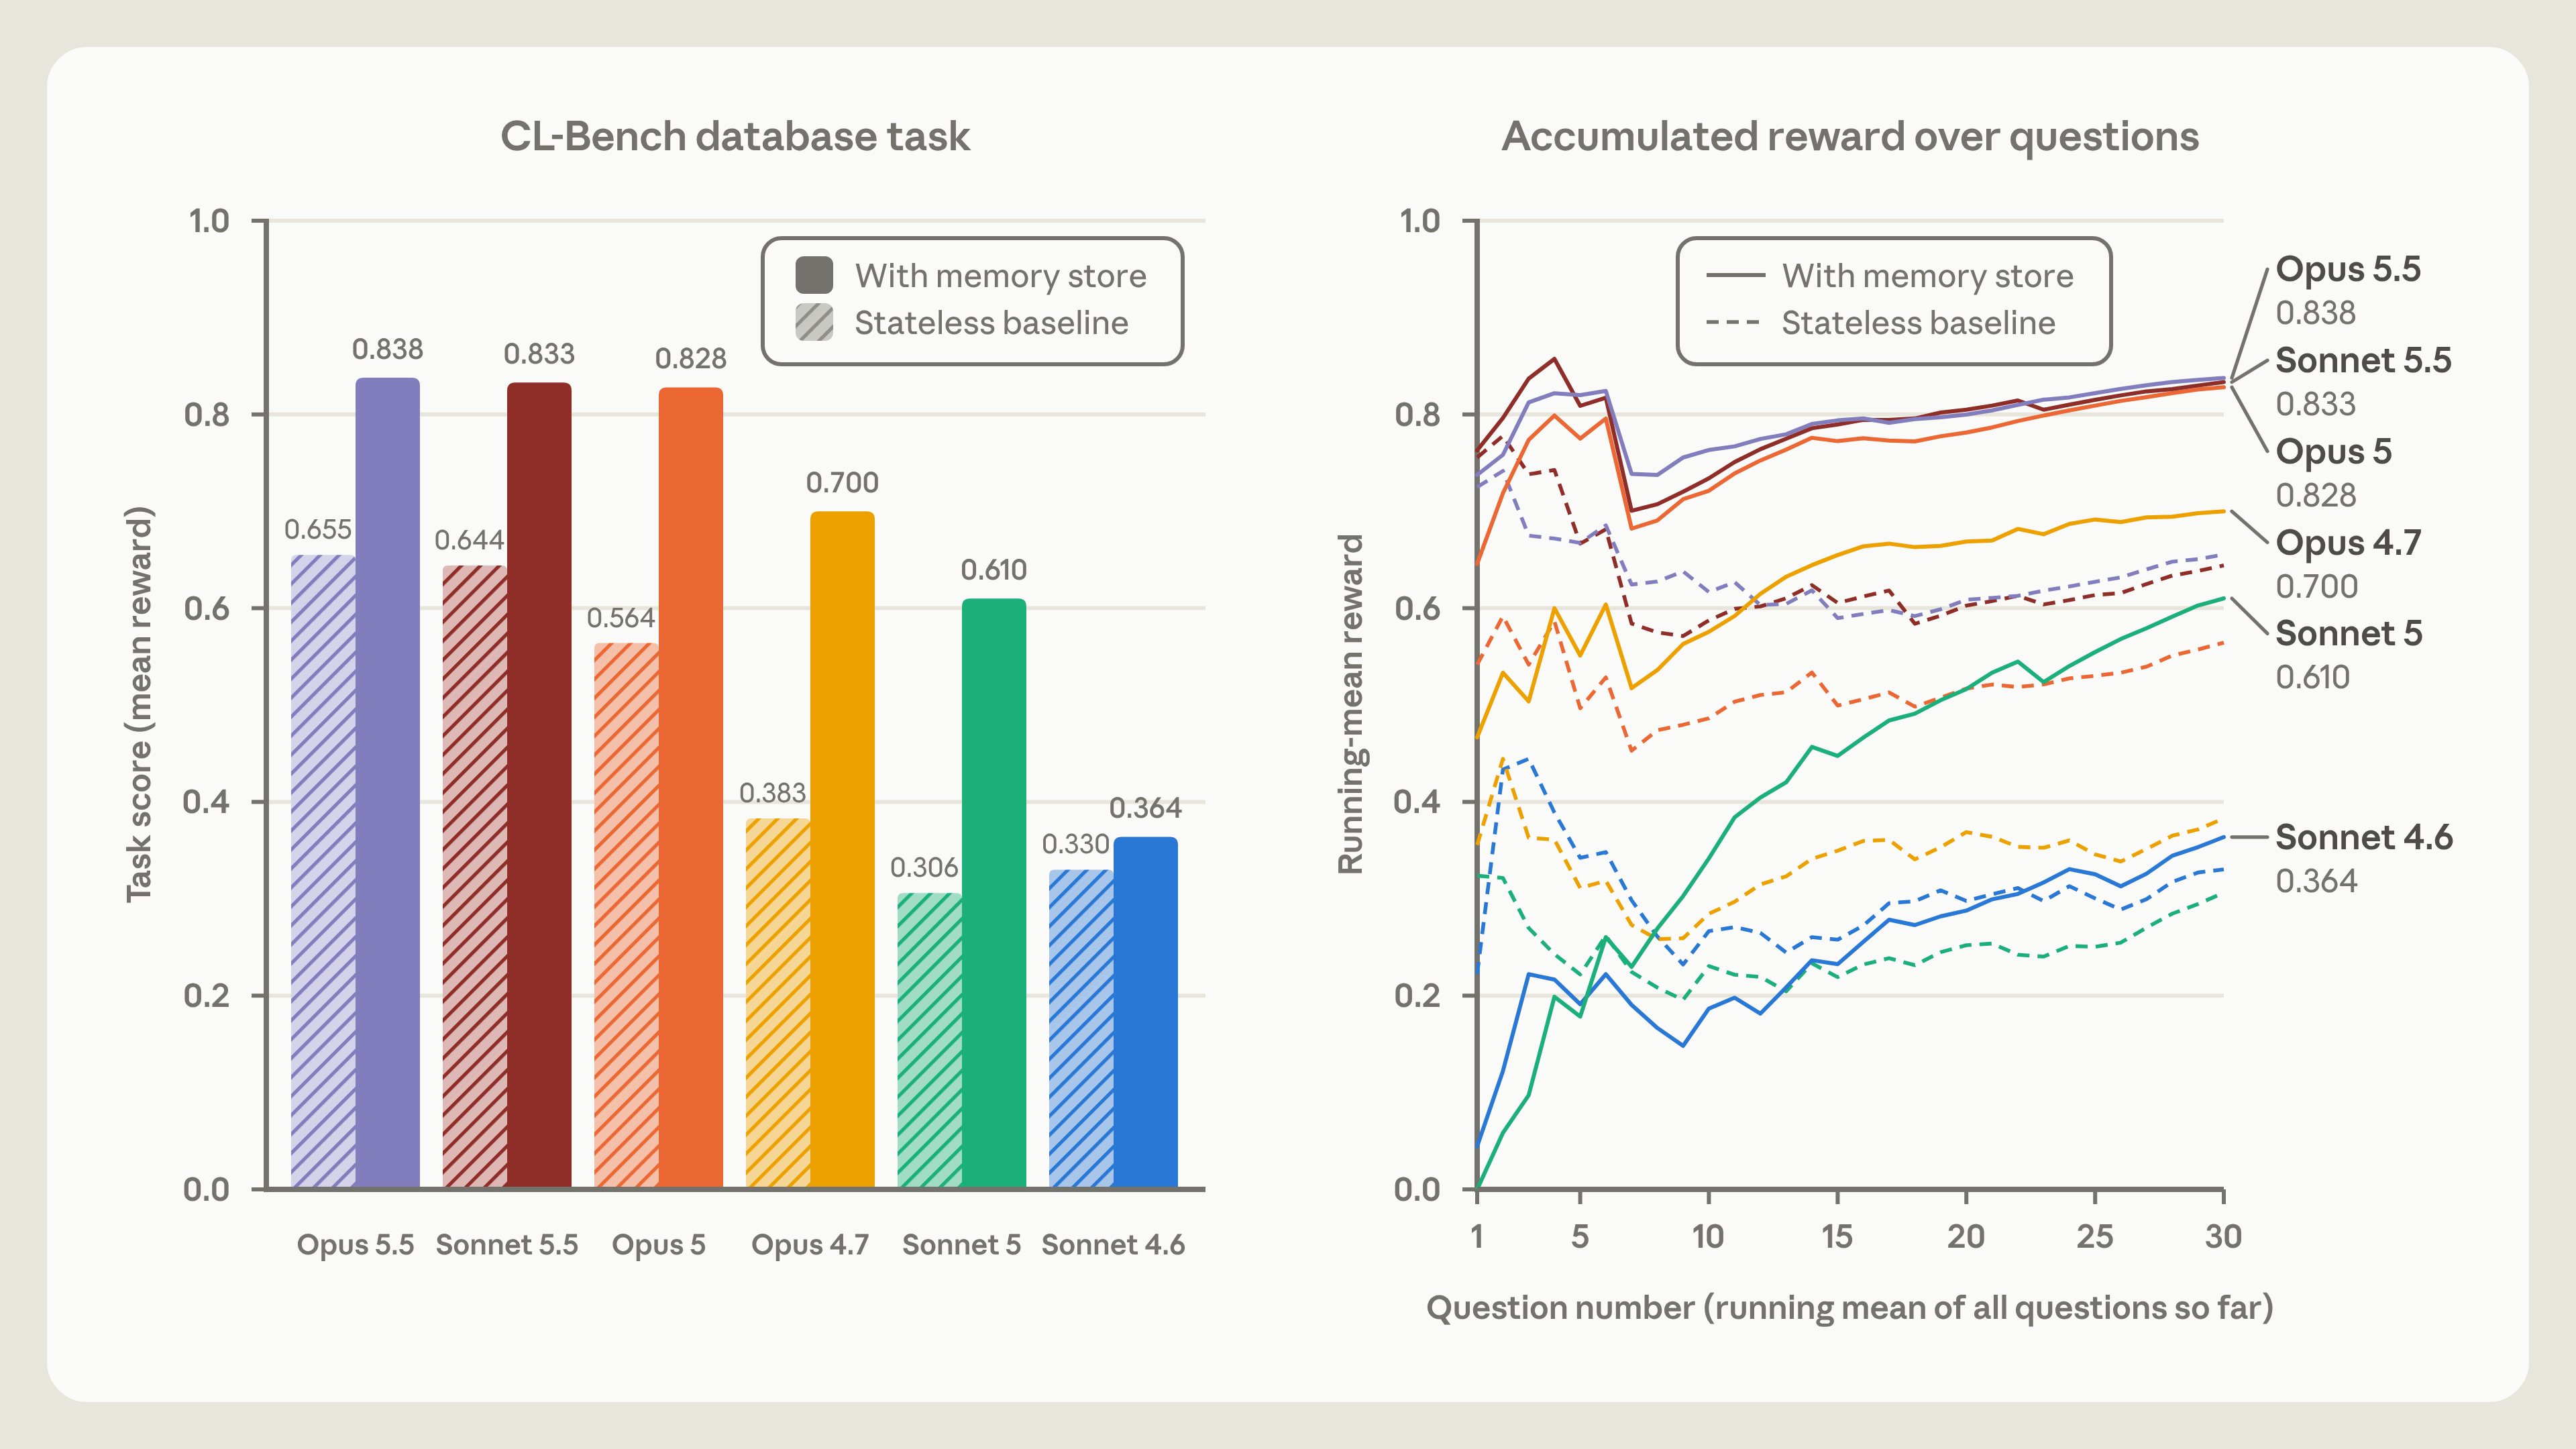
图 3:CL-Bench 数据库任务中,各模型在有无记忆时的平均奖励;右侧展示约 30 道题中的滚动平均变化。
具体分数如下,前一个数值为无记忆基线,后一个为使用记忆后的结果:
- Opus 5.5:0.655,0.838。
- Sonnet 5.5:0.644,0.833。
- Opus 5:0.564,0.828。
- Opus 4.7:0.383,0.700。
- Sonnet 5:0.306,0.610。
- Sonnet 4.6:0.330,0.364。
Opus 5.5 和 Sonnet 5.5 的无记忆基线更高,但加上记忆后,得分与 Opus 5 大致相当。Sonnet 4.6 的提升则很小。给模型一个记忆文件夹,还不够;它得会读取、验证和更新里面的内容。
屏幕上已经有的信息,未必值得再存一遍
《宝可梦 红》的对照展示了另一种区别:模型如何判断什么值得记。
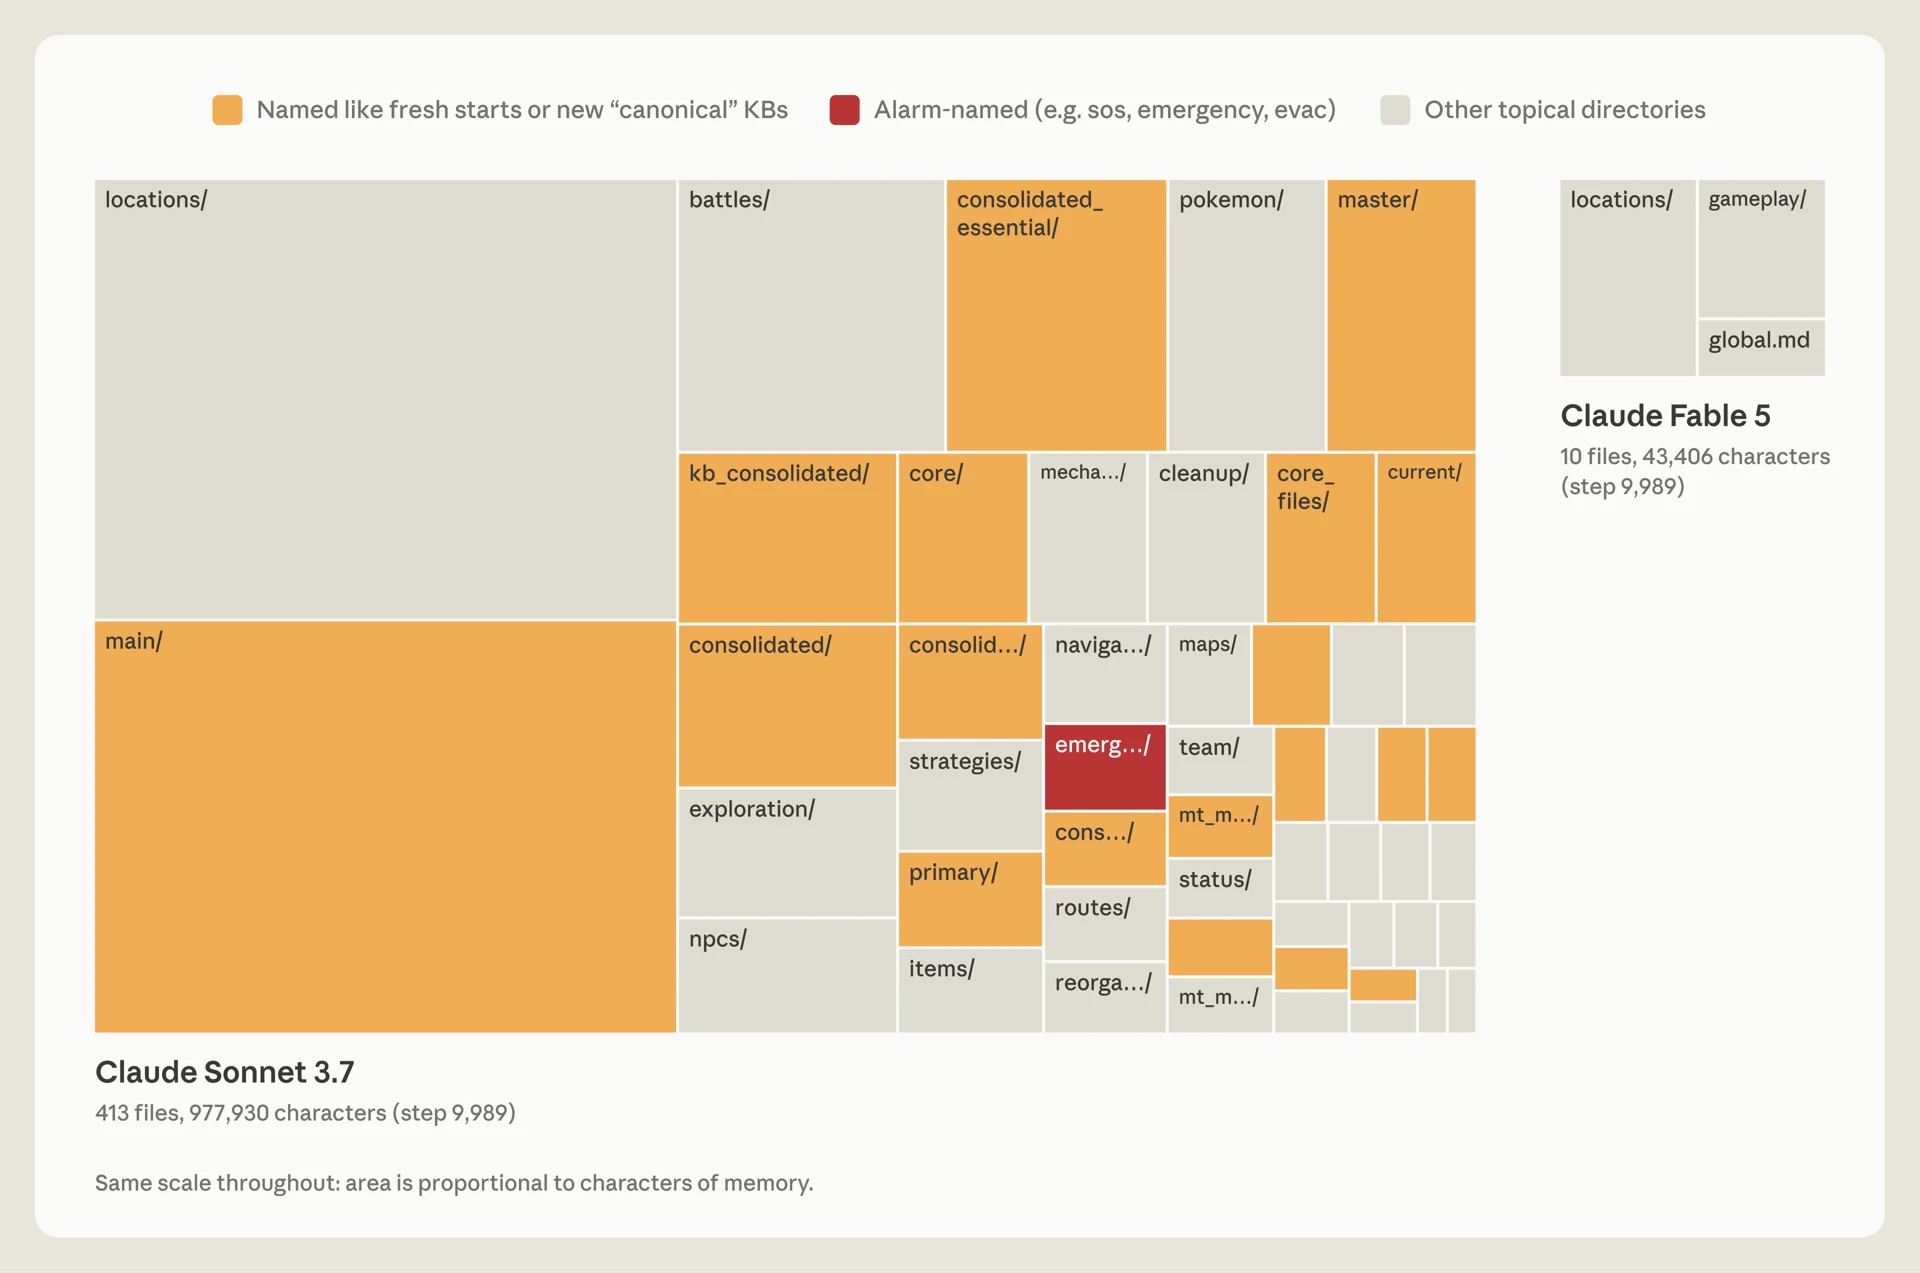
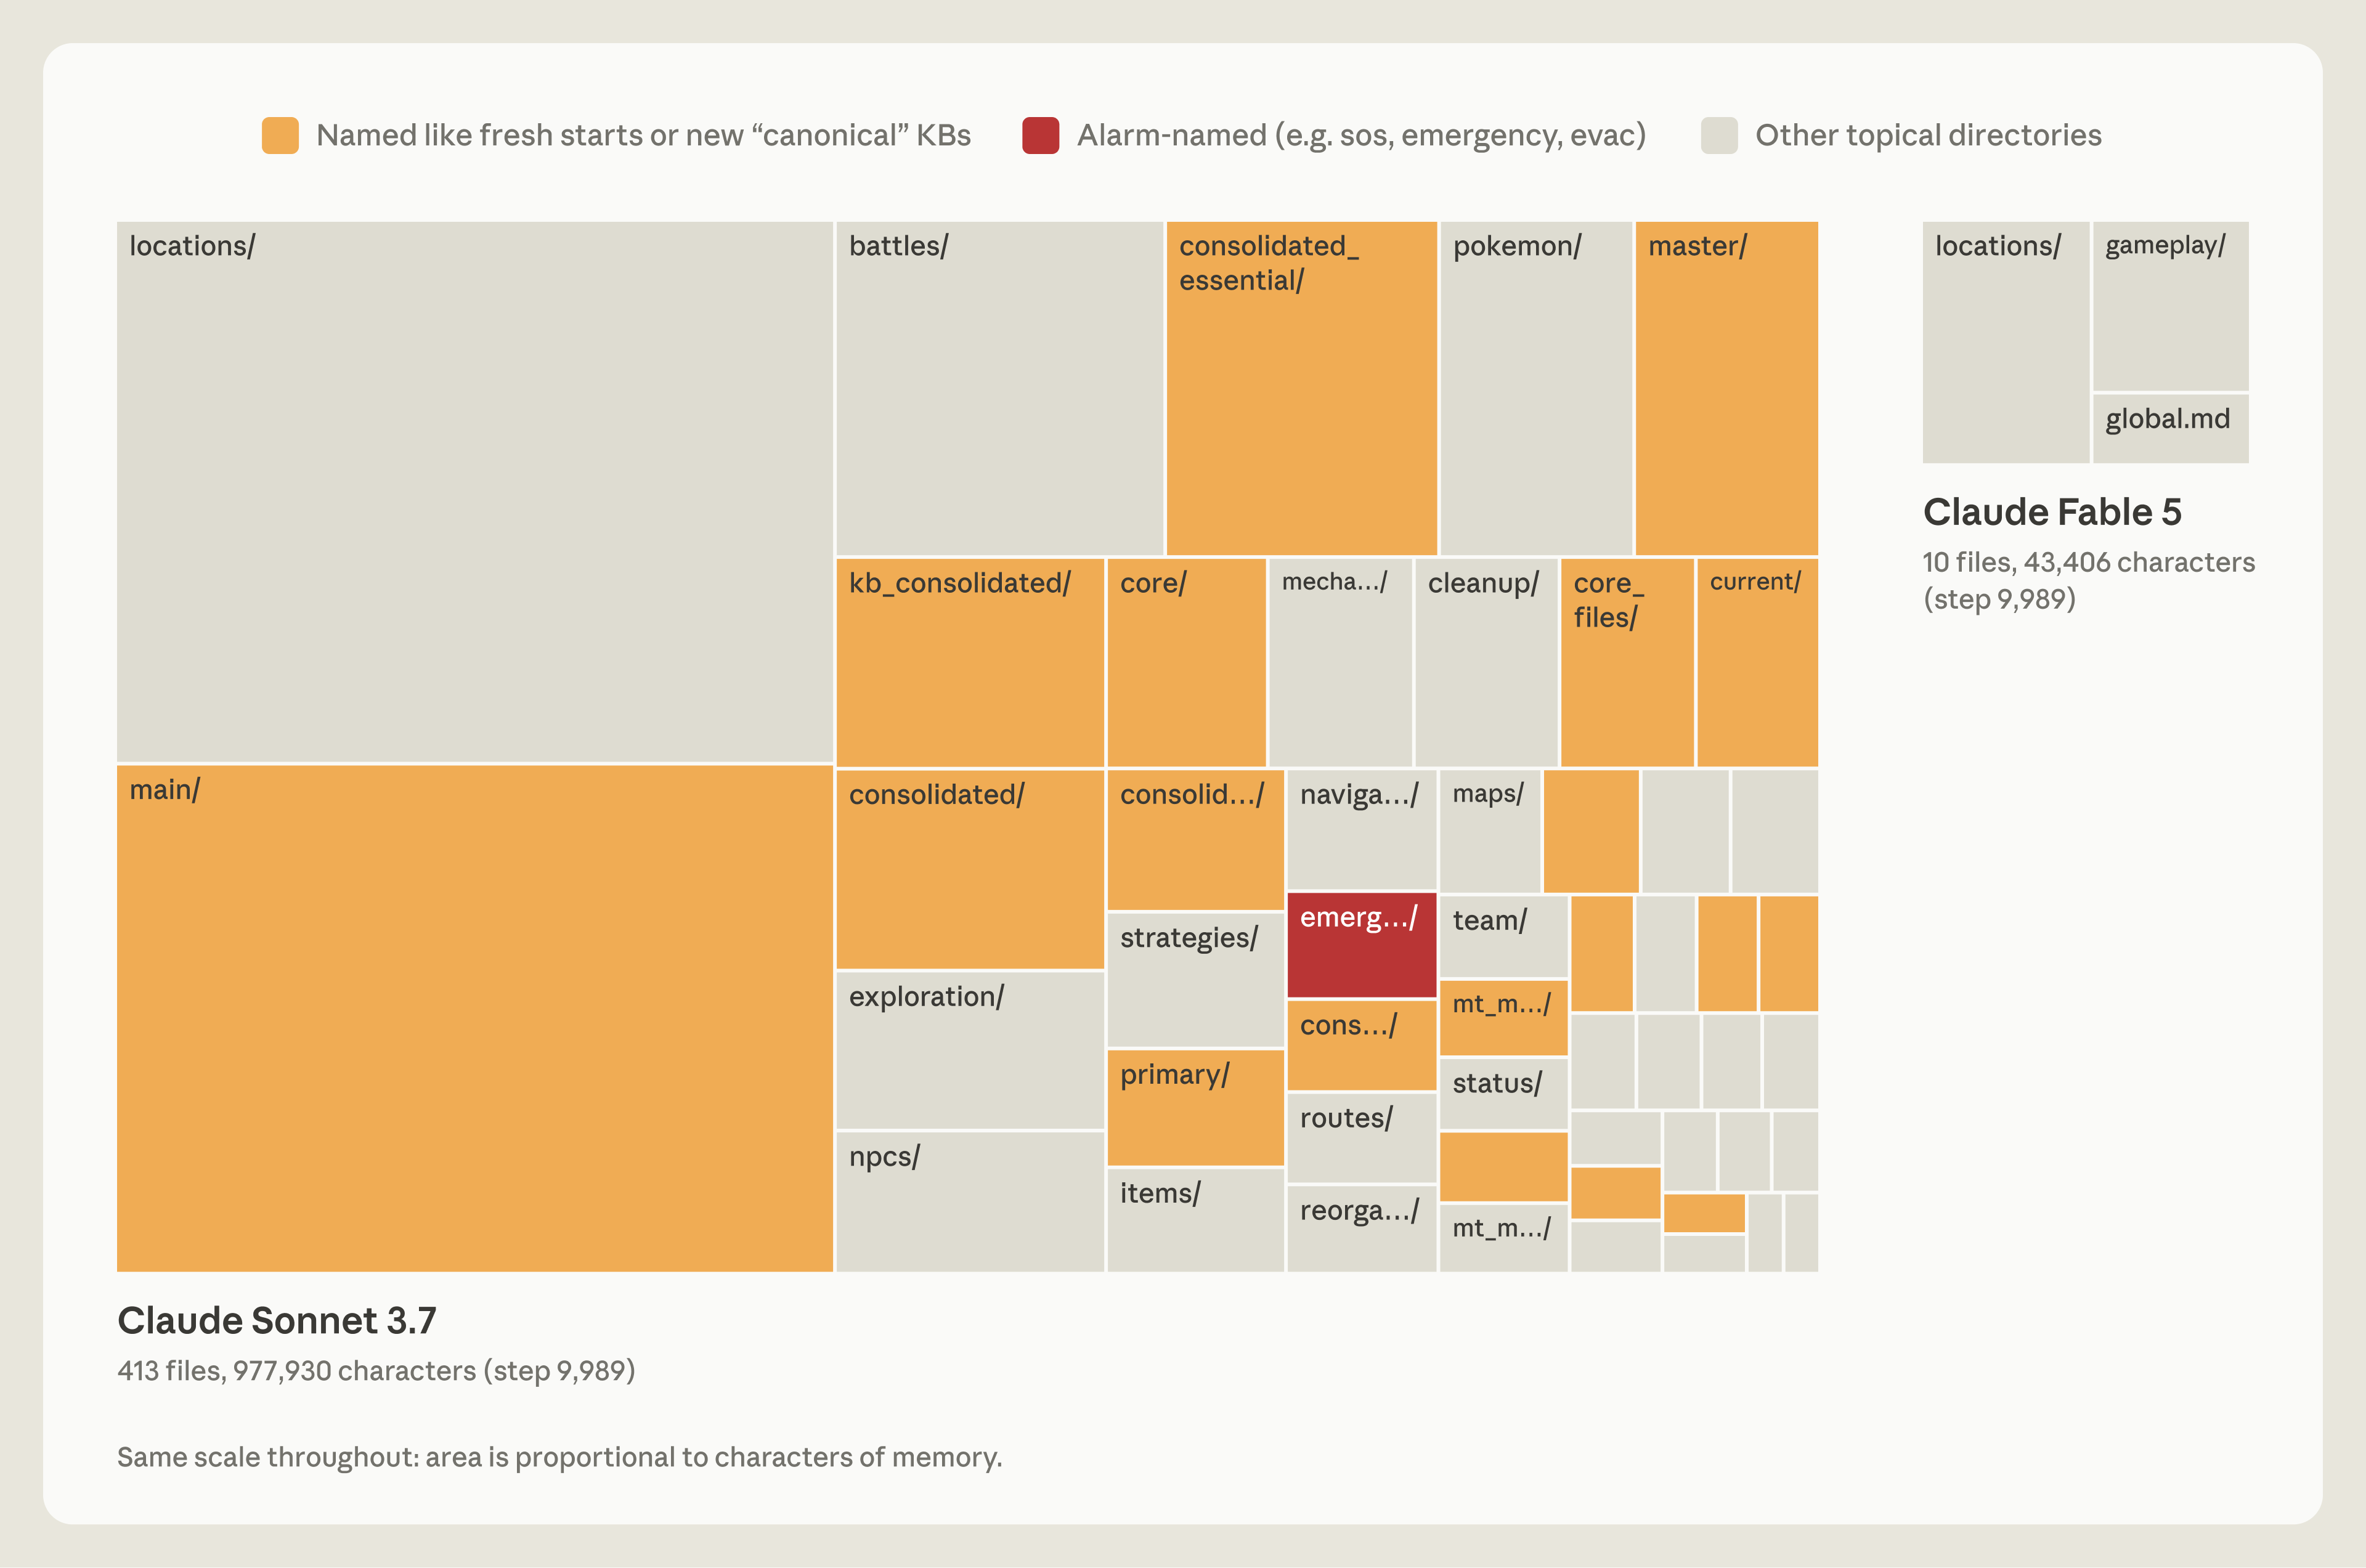
Sonnet 3.7 几乎把所有遭遇都存了下来,战斗、道具、遇到的角色,常常各建一份文件。约 10,000 步时,它留下 413 份文件,散落在 225 个文件夹里,总计 977,930 个字符。
Fable 5 的记忆只有 43,406 个字符:两个文件夹里的 9 份文件,加上顶层的一份 global.md。
媒体未能载入,请通过下方原文链接查看。
图 4:同一比例下,两份宝可梦记忆目录的面积对照。Sonnet 3.7 的记录庞杂,Fable 5 的目录小得多。
金钱余额、当前位置,每回合看屏幕就知道。游戏状态又一直在变,反复保存这些信息,容易留下很快过期的记录。
Fable 5 更倾向于保存屏幕不会直接告诉它的内容:接下来要做什么、怎样通过某条路线、哪些策略试过有效。它把当前目标、道馆计划和记忆使用规则放在 global.md,把路线计划与游戏策略分开保存。
例如,它连续 7 次用精灵球捕捉鲤鱼王失败后,写下了一条经验:连续失败达到 3 次或更多,就改变按键时机,在菜单步骤之间多等待一下。它还记录,调整后立刻捕获成功。这是那次运行里总结出的经验,不能据此认定为游戏的普遍机制。
Opus 5.5 也采用了类似做法,用一个小文件夹跟踪当前目标和下一步,边玩边改,最终通关。
同一句“只记失败”,对强模型也可能起反作用
该怎样告诉 Claude 使用记忆?研究者发现,提示需要与模型能力匹配。
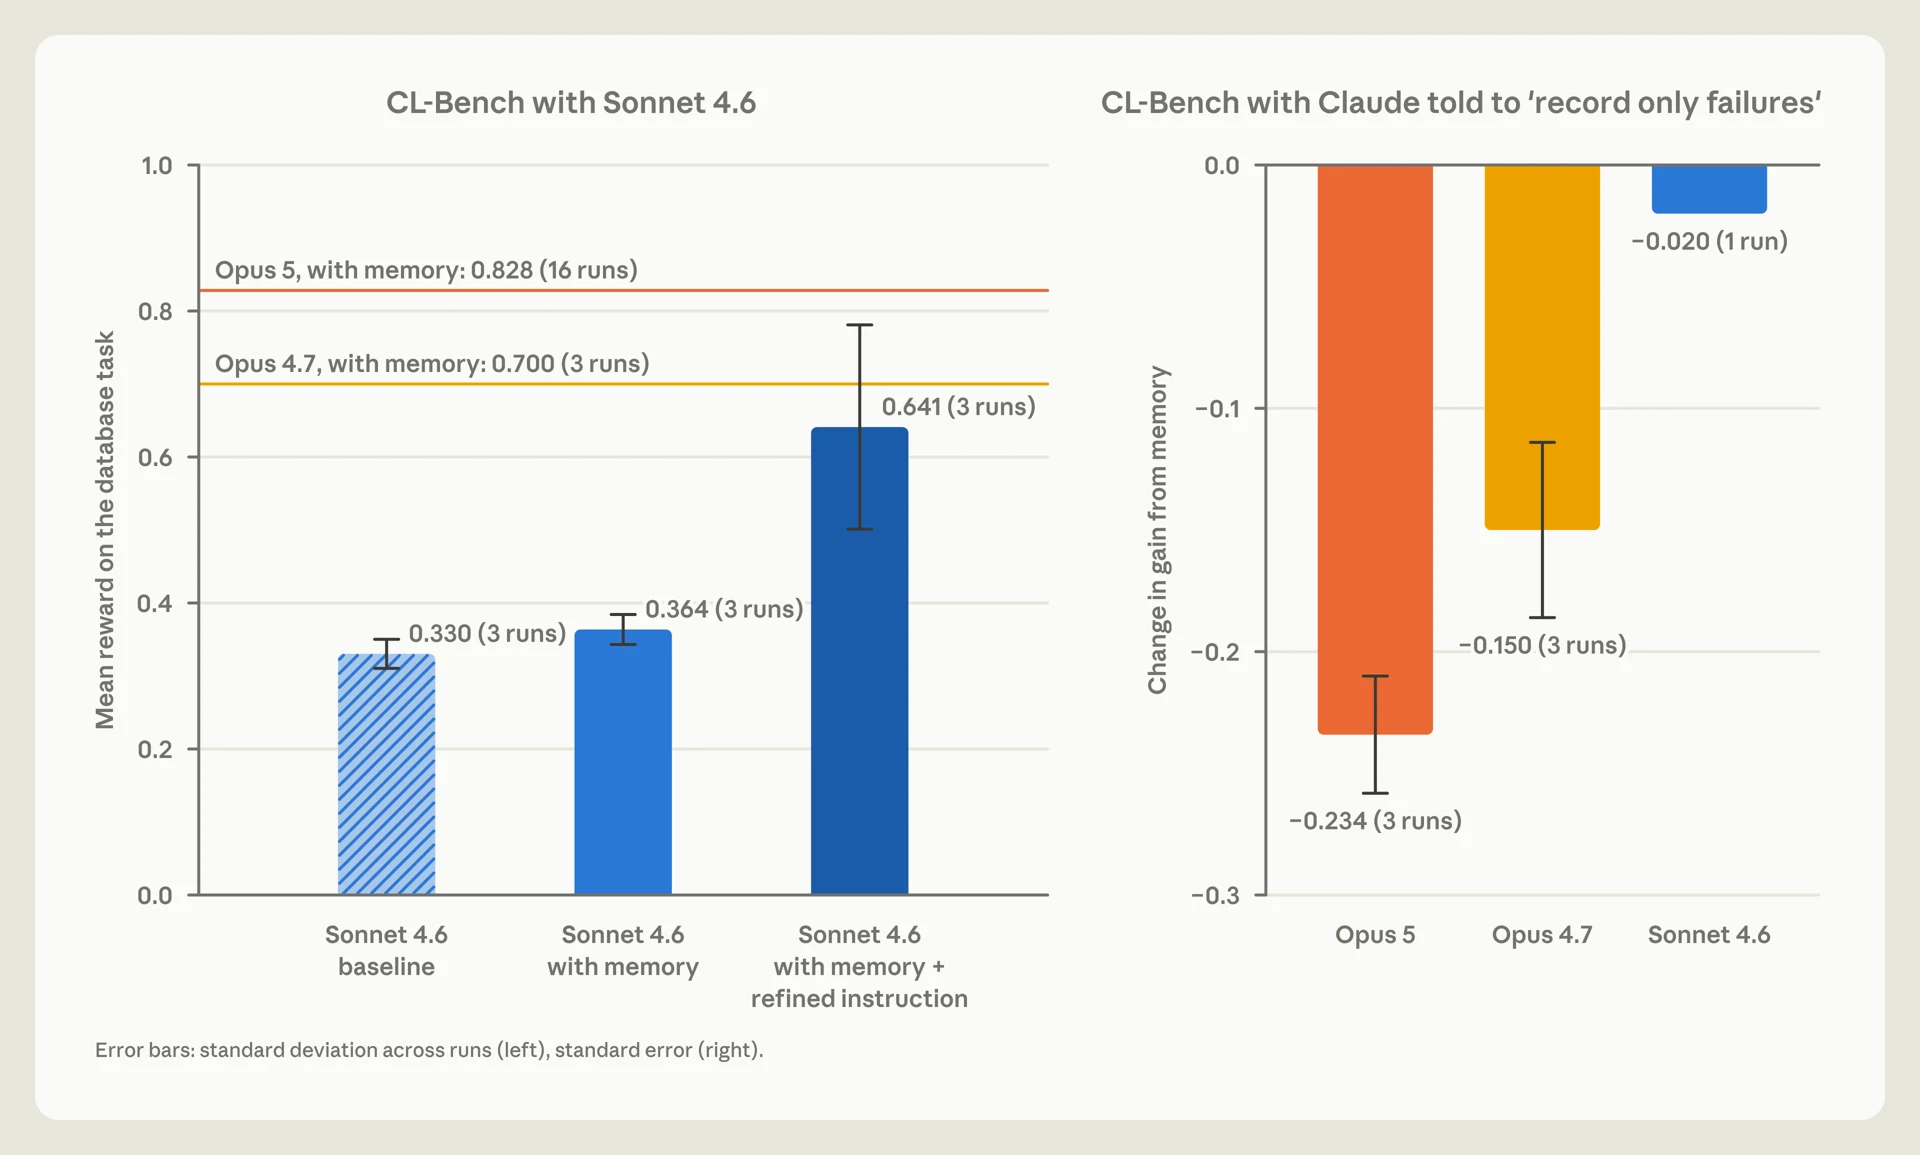
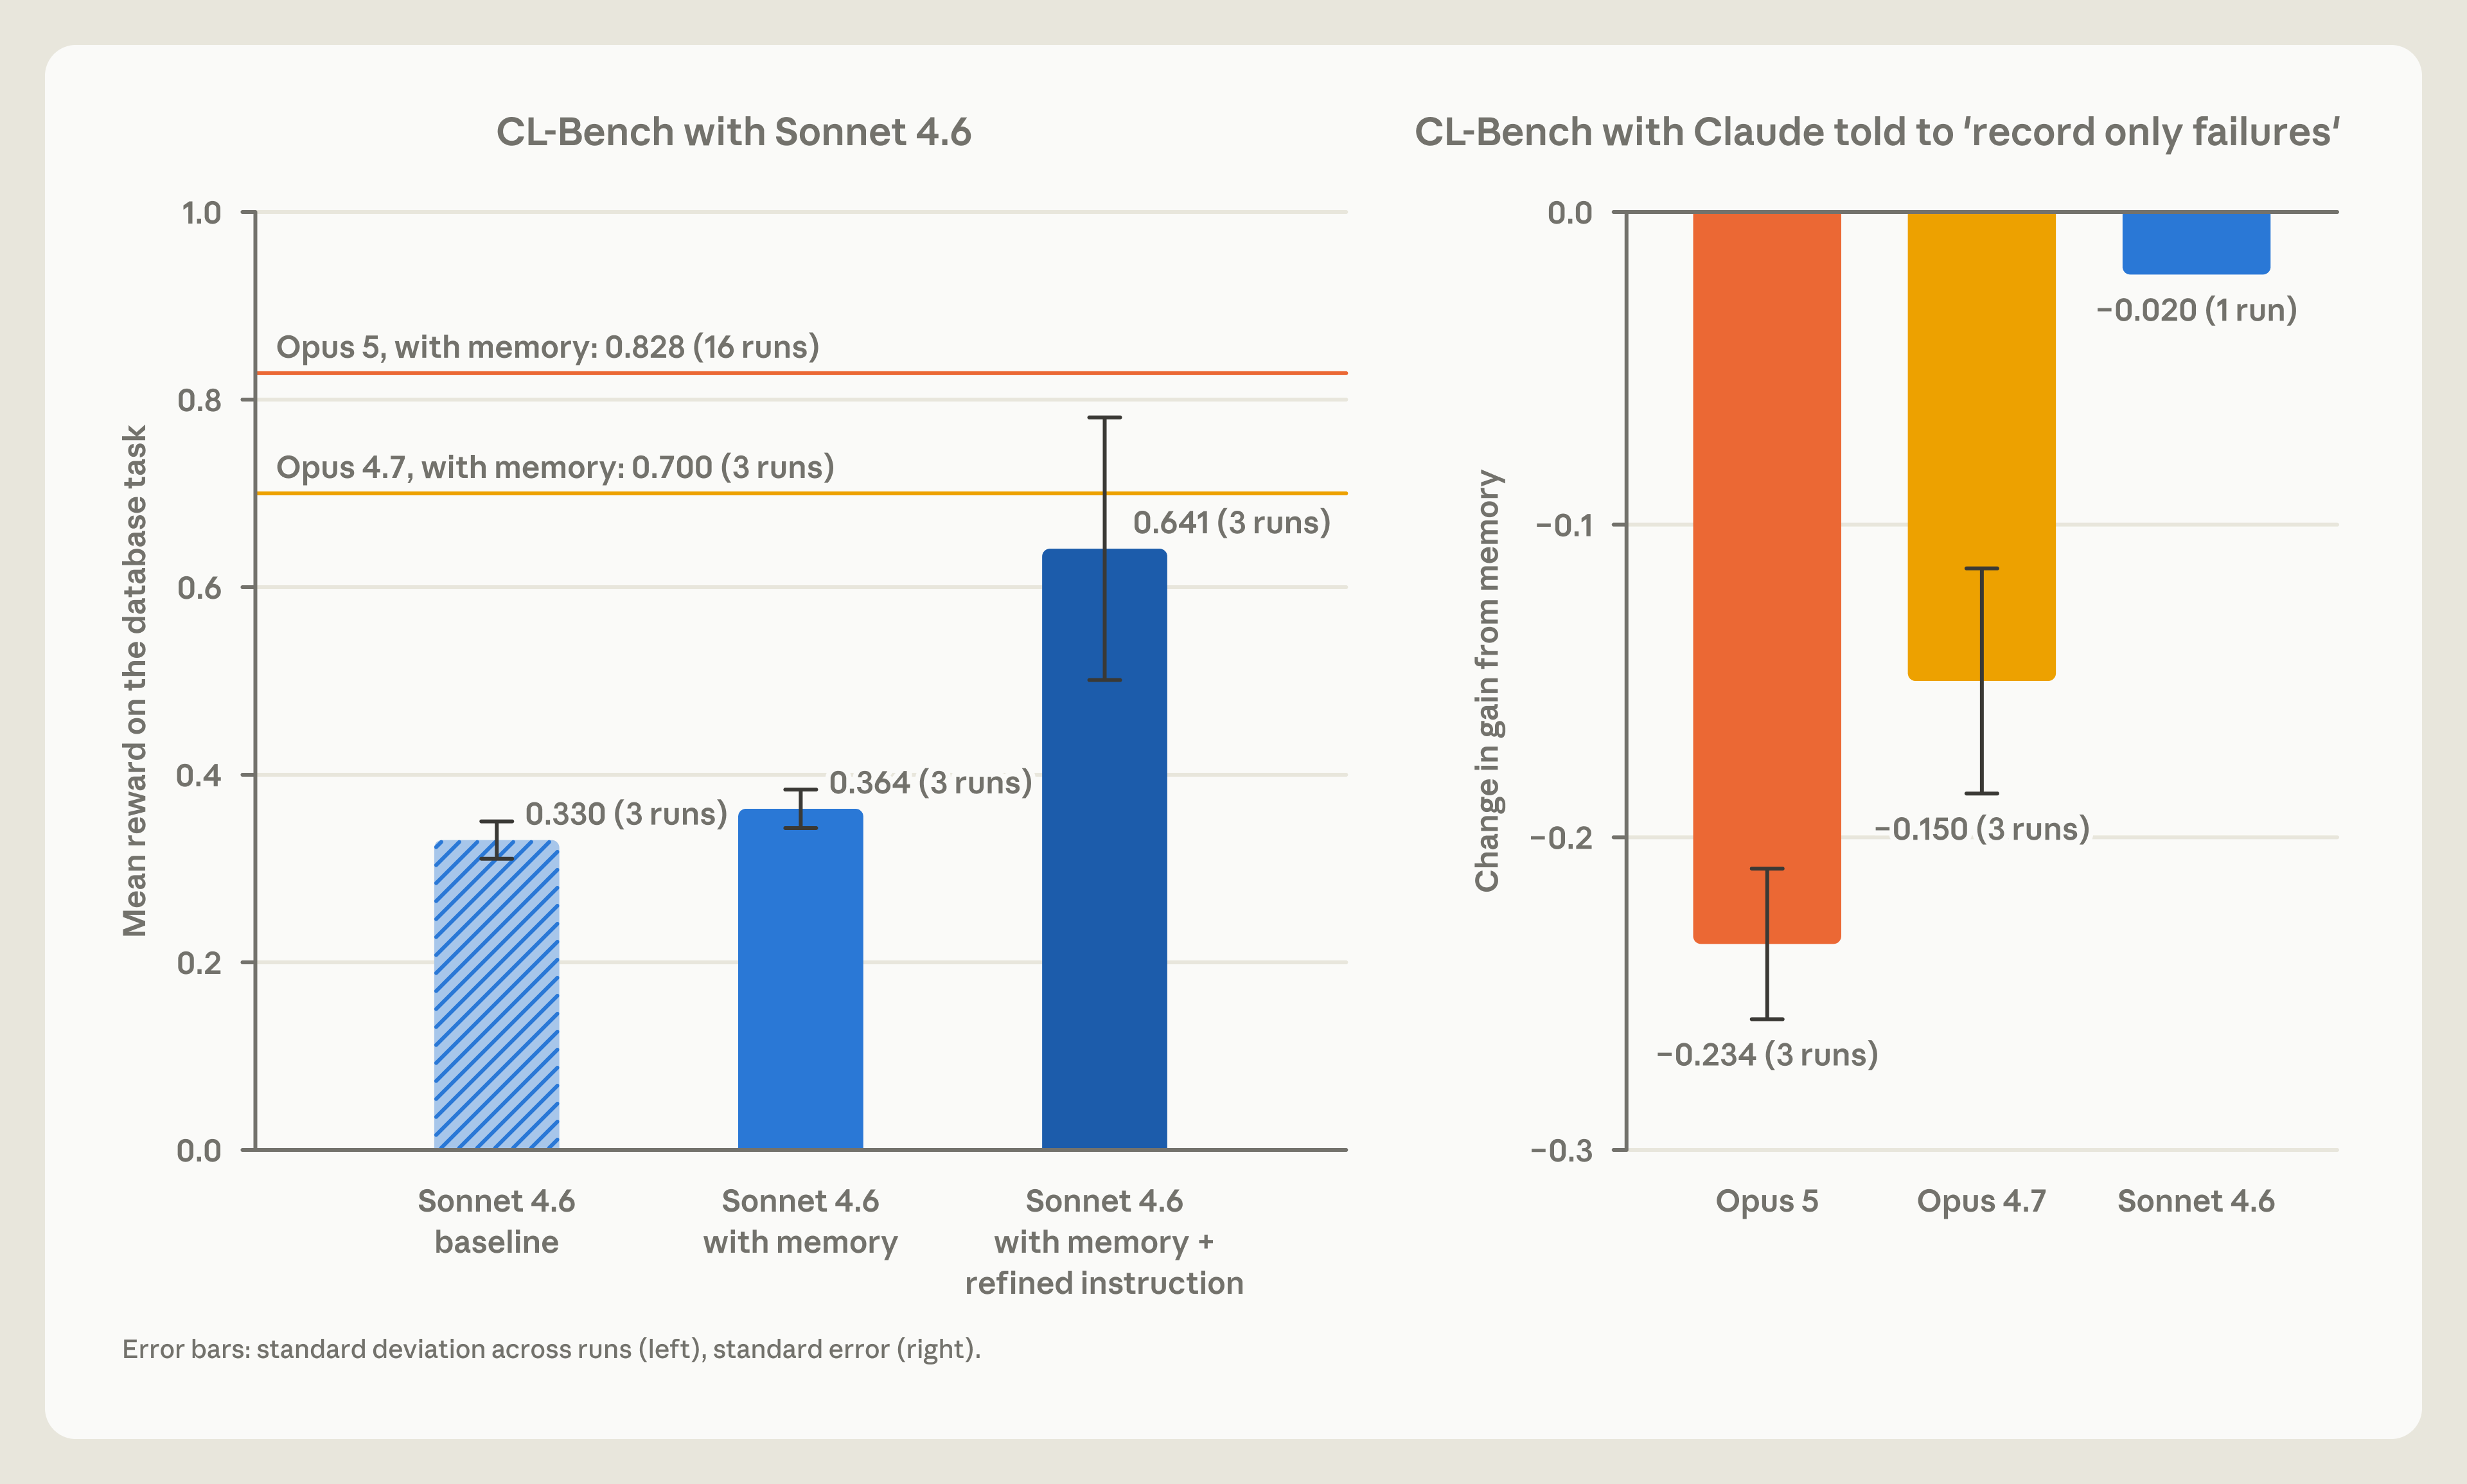
在 CL-Bench 上,Opus 4.7 和 Opus 5 只需知道有一个记忆文件夹可用,就能从中获益。若再强制规定“只记录失败”,两者原本从记忆中得到的提升,反而损失了很大一部分。
对 Sonnet 4.6,问题又不同。它经常不读记忆,也不验证答错原因的猜测。明确要求它作答前读取笔记、检验推测后,平均奖励从仅使用记忆时的 0.364,提高到 0.641;无记忆基线为 0.330。
媒体未能载入,请通过下方原文链接查看。
图 5:左侧为 Sonnet 4.6 加入读写与验证提示后的变化;右侧为“只记录失败”对记忆增益的影响。
“只记录失败”带来的记忆增益变化,Opus 5 为负 0.234,Opus 4.7 为负 0.150,Sonnet 4.6 为负 0.020。图中同时给出参考:Opus 4.7 使用记忆时为 0.700,Opus 5 为 0.828。
Sonnet 5 在没有额外提醒时,10 次里有 9 次会在回答前先读记忆;Sonnet 4.6 的比例不到一半。较旧模型需要补上基本动作,更强模型则可能受限于过细的固定规则。
Anthropic 对前沿模型通常只给简单指引:用户要求时,或有明显值得保留的内容时,创建笔记。其余判断交给 Claude。
一条记错的位置,能让智能体反复走回头路
笔记保留下来后,错误也可能跟着保留下来。Dreaming 的一个用途,就是拿笔记与原始会话记录核对。
媒体未能载入,请通过下方原文链接查看。
图 6:回到原始日志检查记忆,找出并修正笔记中的错误。
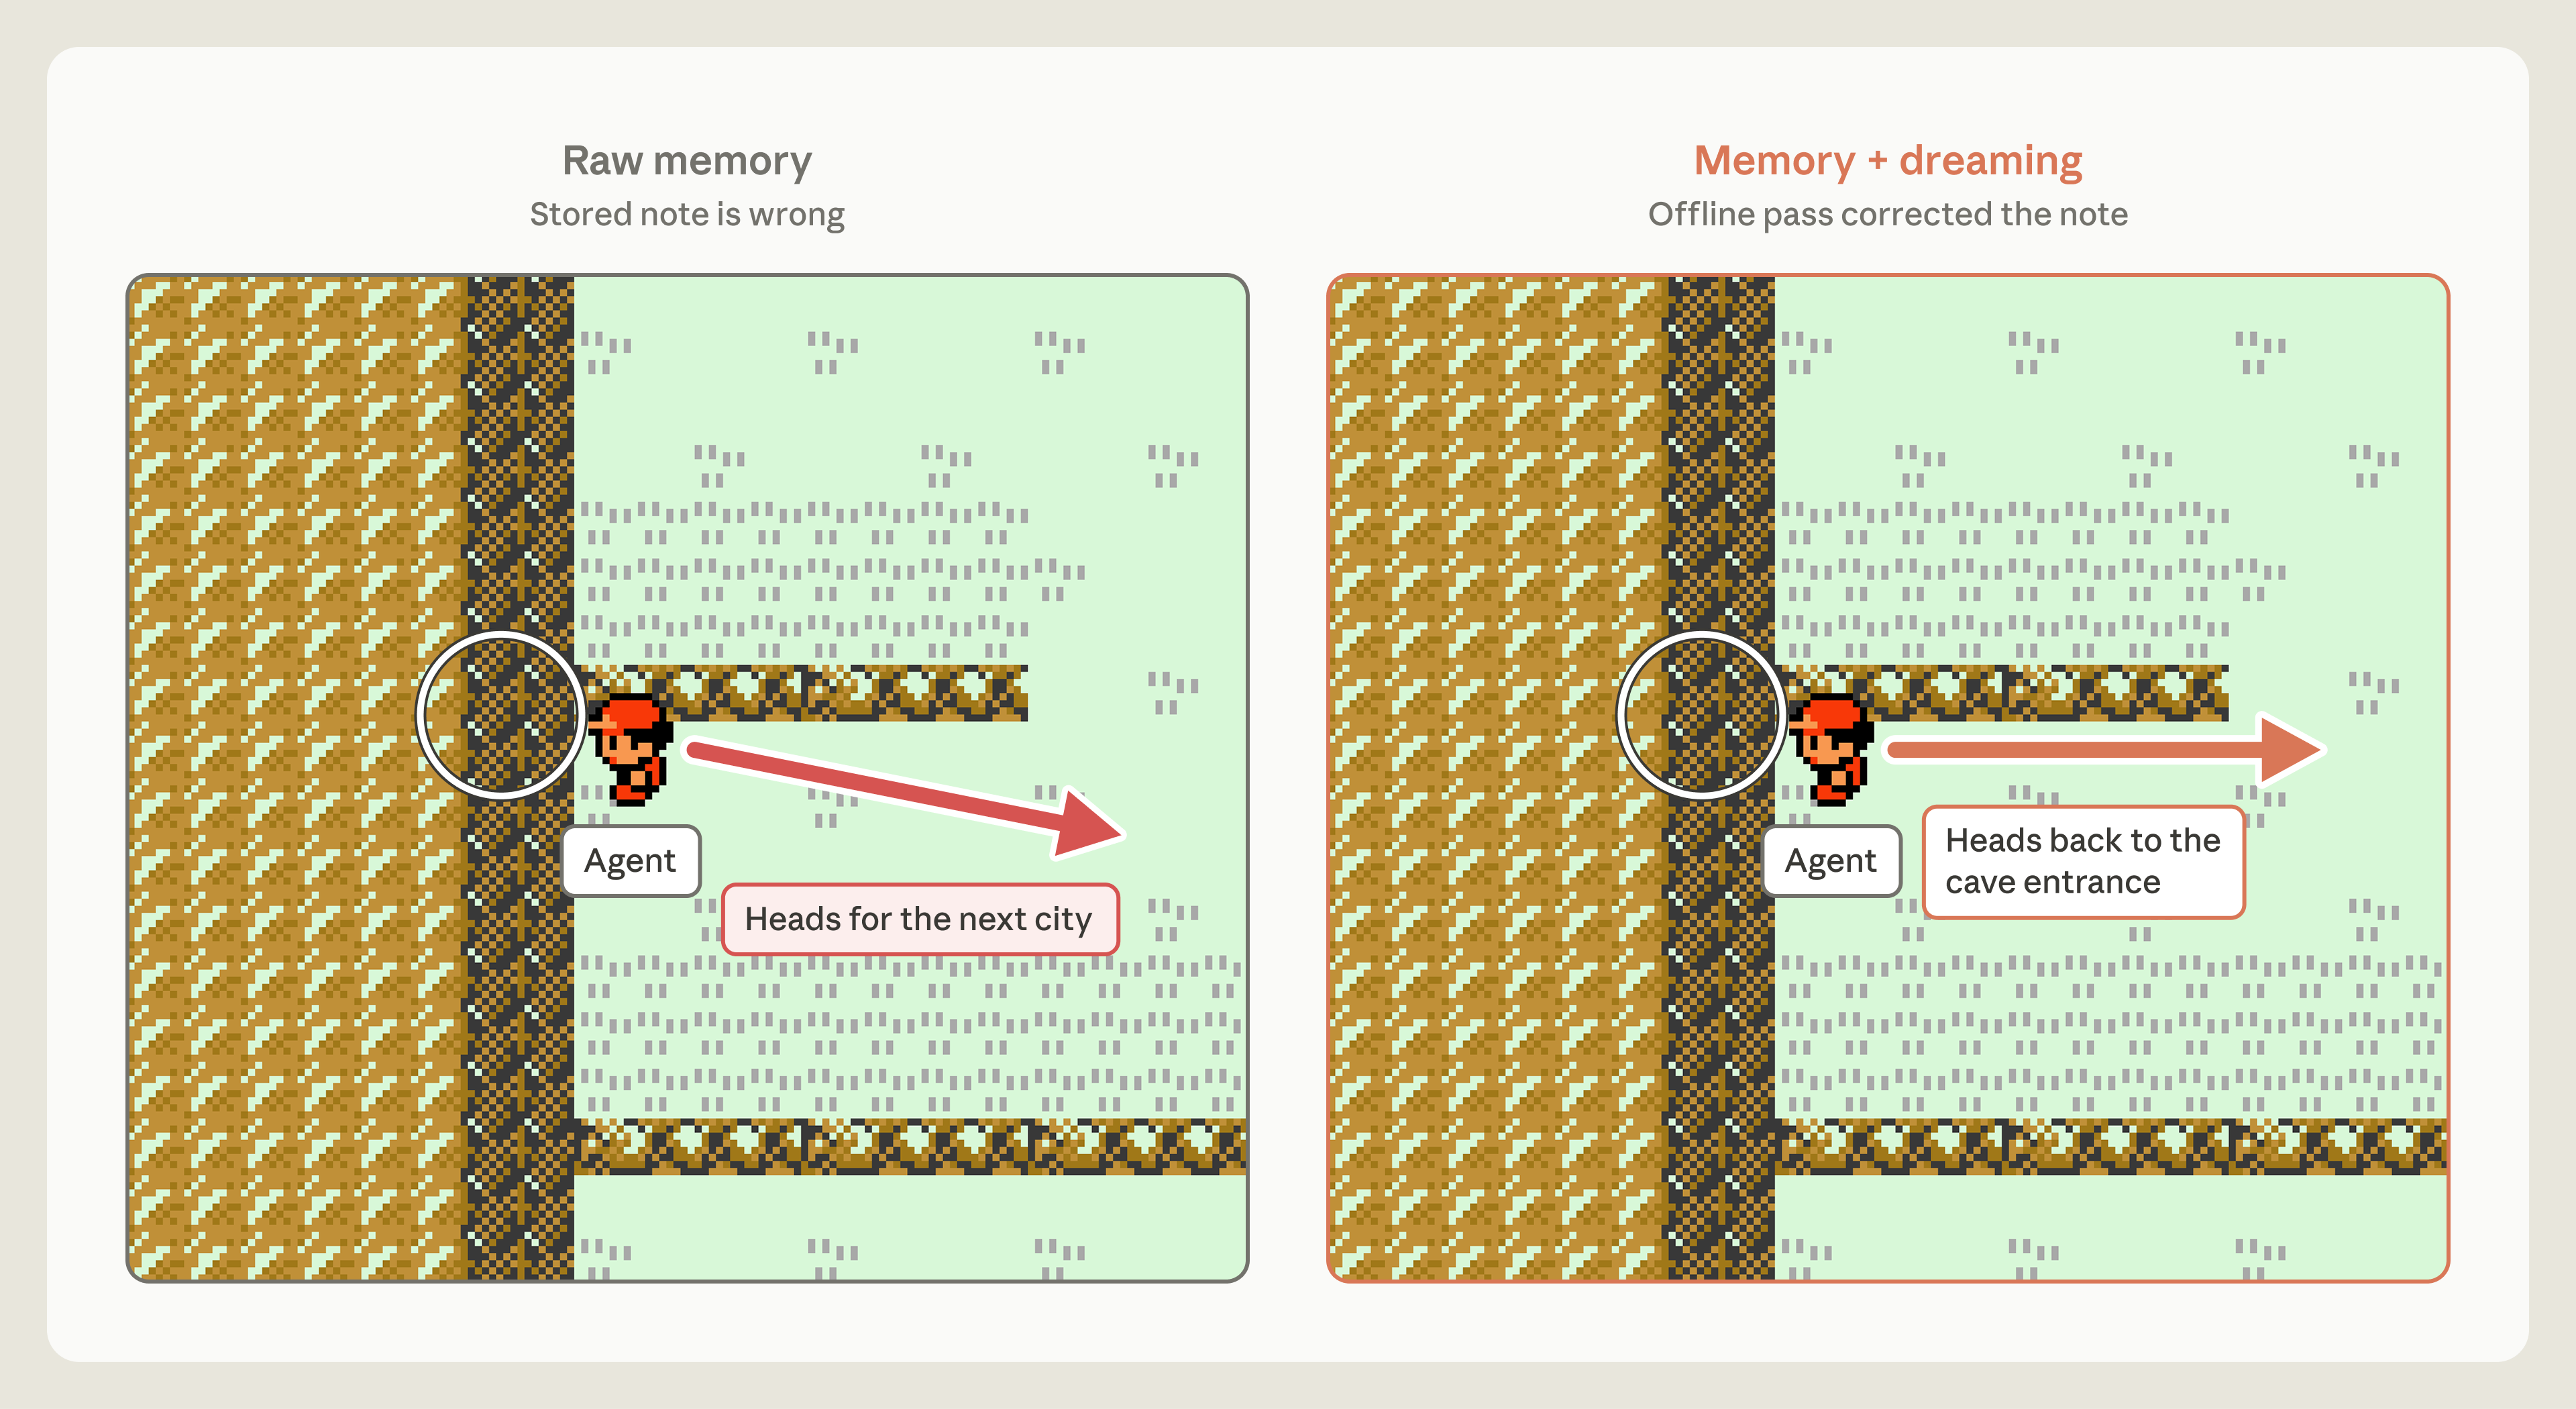
研究者在《宝可梦 红》里遇到过一个例子。玩家需要穿过月见山,入口在西侧,出口在东侧。入口附近有一道只能往下跳的岩架,跳下去就会掉回来时的路线。
Claude 把入口附近的宝可梦中心记成了位于东侧。于是它走出中心后,判断月见山已经走完,并在笔记里标上完成。几步之后,它跳下岩架,回到了先前的路线。
导航工具没有显示这次坠落。Claude 又给错误补了一个解释,认为只是向西走过了头,自己此前所在的位置本来就正确。
媒体未能载入,请通过下方原文链接查看。
图 7:左侧为受错误笔记影响的路线判断;右侧为核对记录、纠正笔记后返回入口的路线。
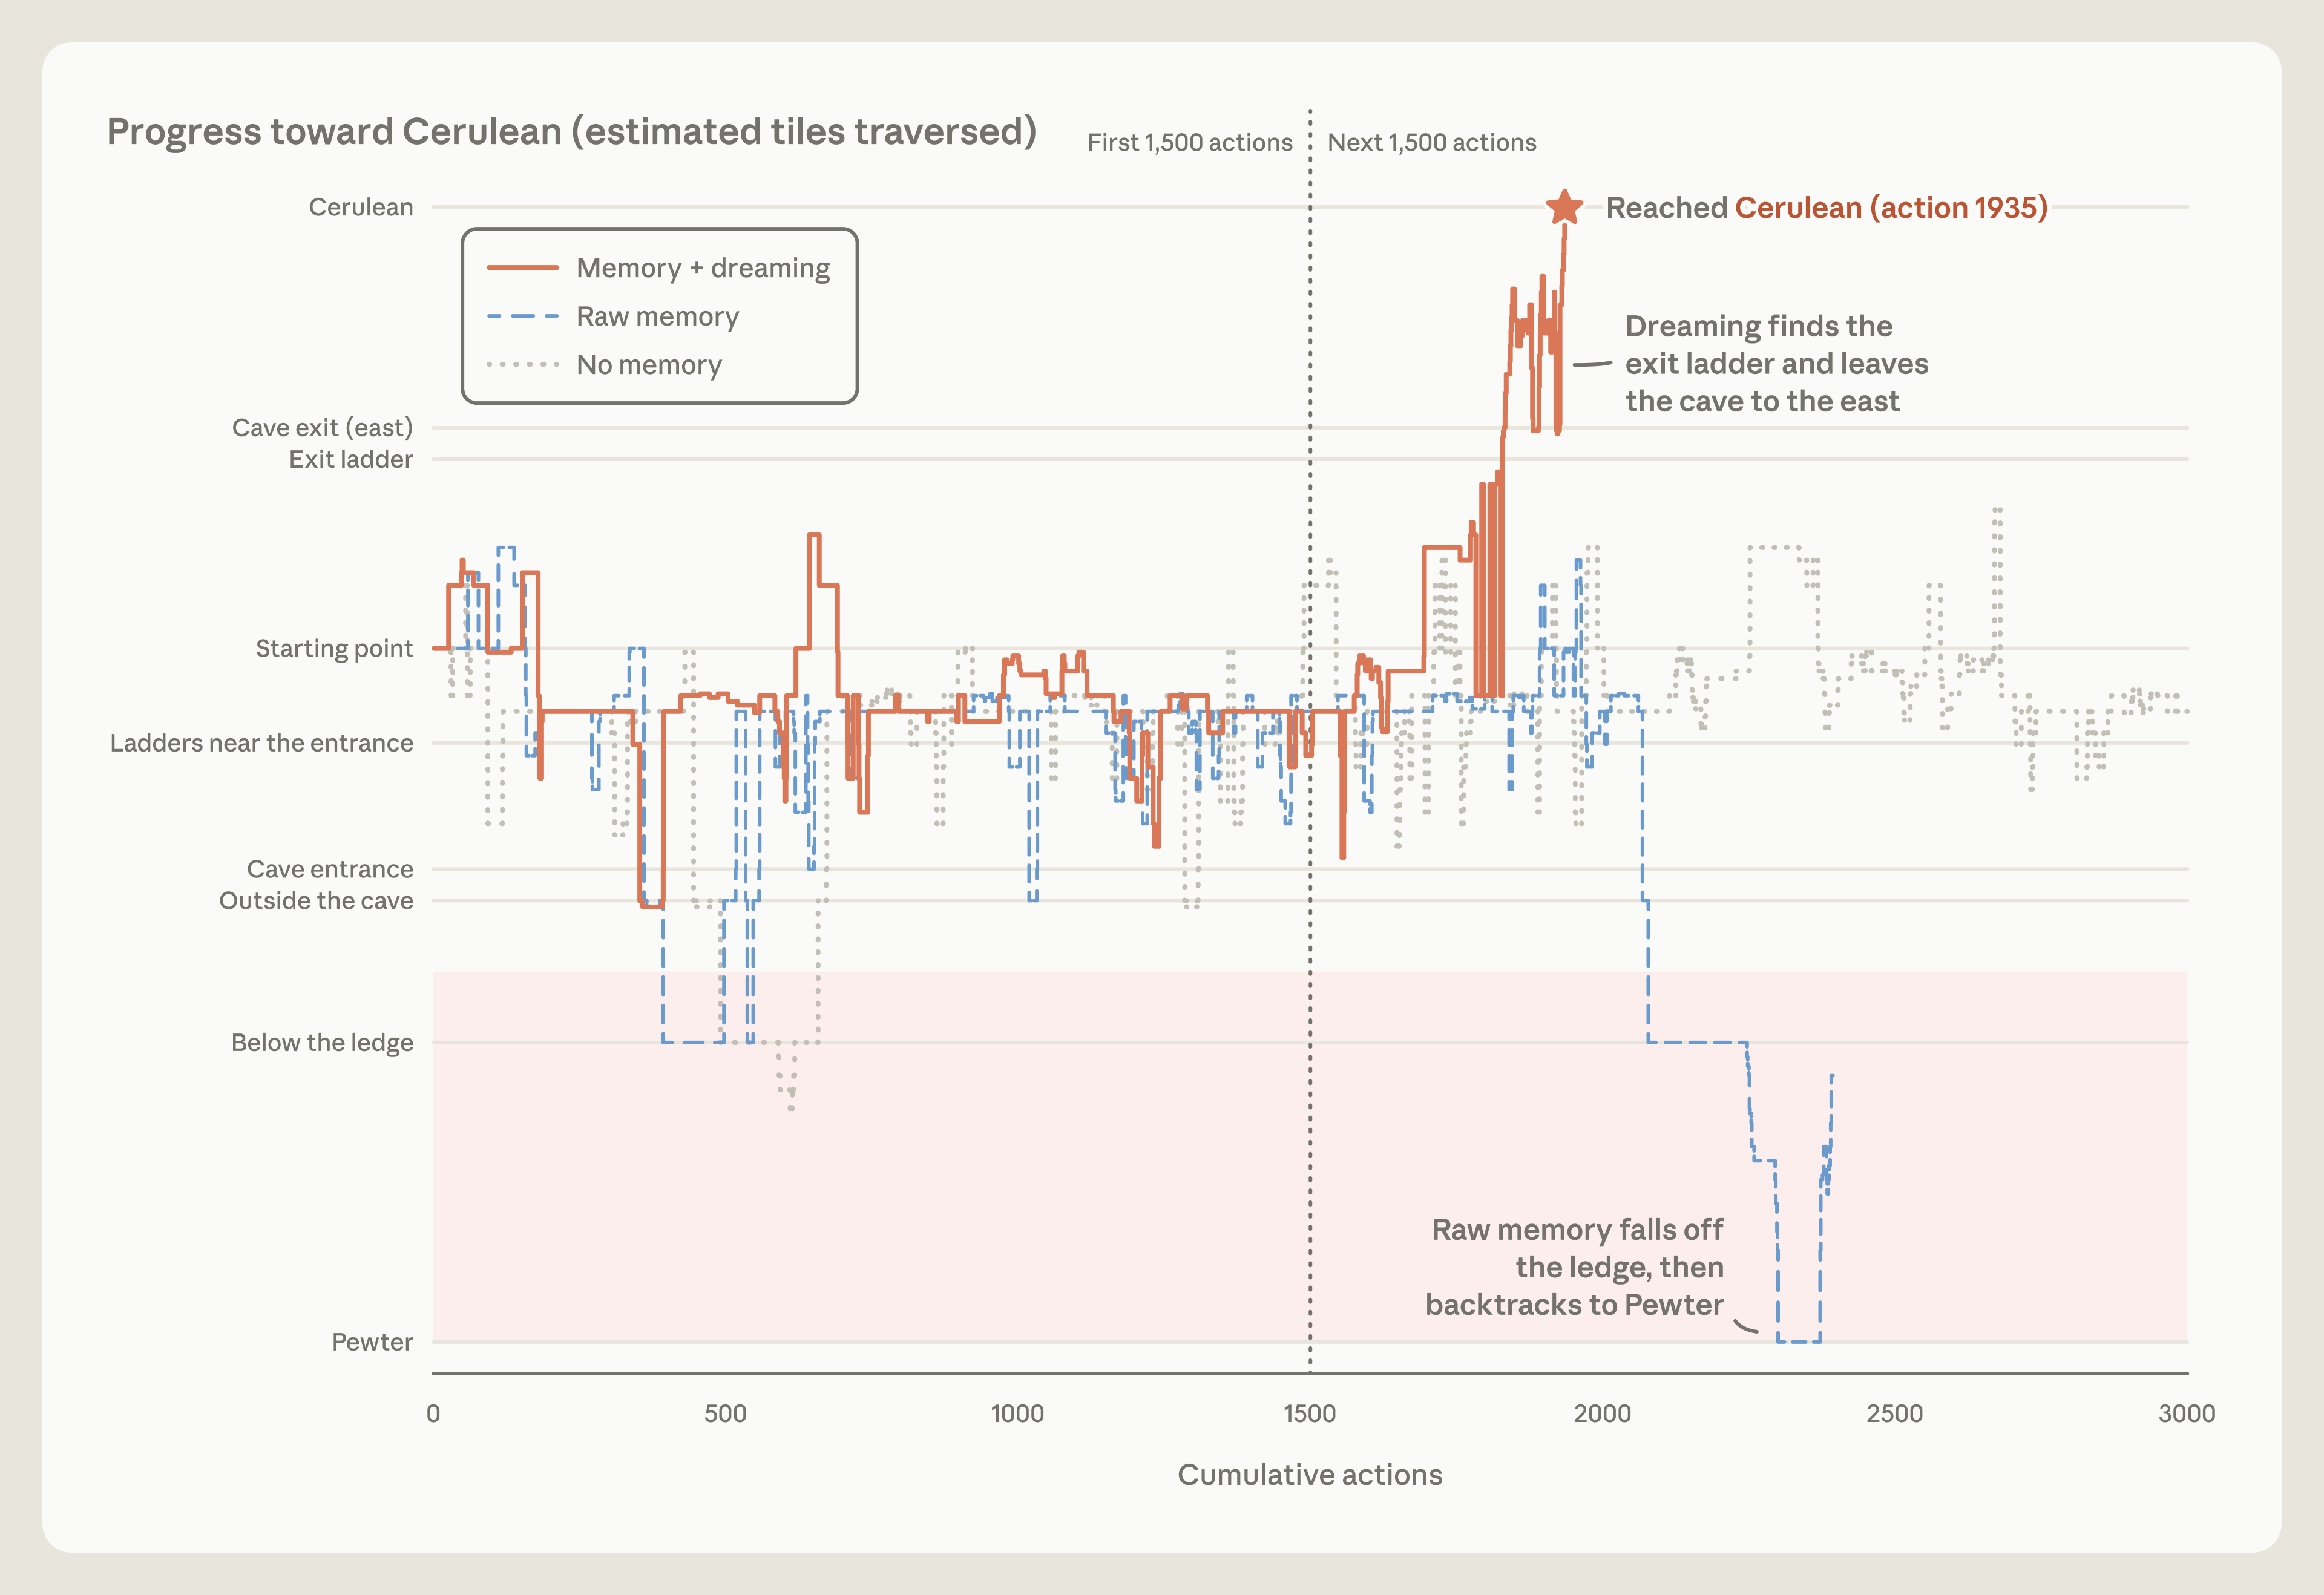
研究者随后让 Claude 对这份记忆运行 dreaming。它回看会话记录,发现宝可梦中心的位置记错了,改写笔记,之后直接回到月见山,最终到达华蓝市。
未纠正笔记的那次运行,Claude 三次掉回旧路线。第三次失败后,它表示想停止循环,实验的自动回复要求继续,它便一路退回尼比市,准备疗伤补货。运行结束时,它仍未到达华蓝市。
媒体未能载入,请通过下方原文链接查看。
图 8:约 3,000 次累计动作内的进度对照。加入 dreaming 的运行在第 1,935 次动作到达华蓝市,另外两条运行未到达。
这次实验提供了一个具体的纠错案例。它说明原始日志可以作为核对笔记的依据,但并未证明 dreaming 能可靠修复所有类型的记忆错误。
知识库配合搜索,比单独依赖知识库更有效
记忆增加后,Claude 还可以把零散笔记整理成带链接的知识库,也就是文章里的 wiki。每个页面汇集一个主题,链接指向其他笔记,方便后续寻找。
媒体未能载入,请通过下方原文链接查看。
图 9:Dreaming 把日志与笔记整理为带链接的知识库,帮助后续会话定位信息。
研究者用 Stainless 的内部文档做实验。Anthropic 在五月收购了这家公司,这批语料约有 35 万个文件、4.2 亿个词元。他们围绕语料制作 25 道题,给 Opus 5 智能体搜索工具,并让它在 128 个会话中建立知识库。
每轮继续前一轮的工作,通过共享日志协调:搜索文件、写页面、纠正内容、合并重复项,并回到来源核查说法。
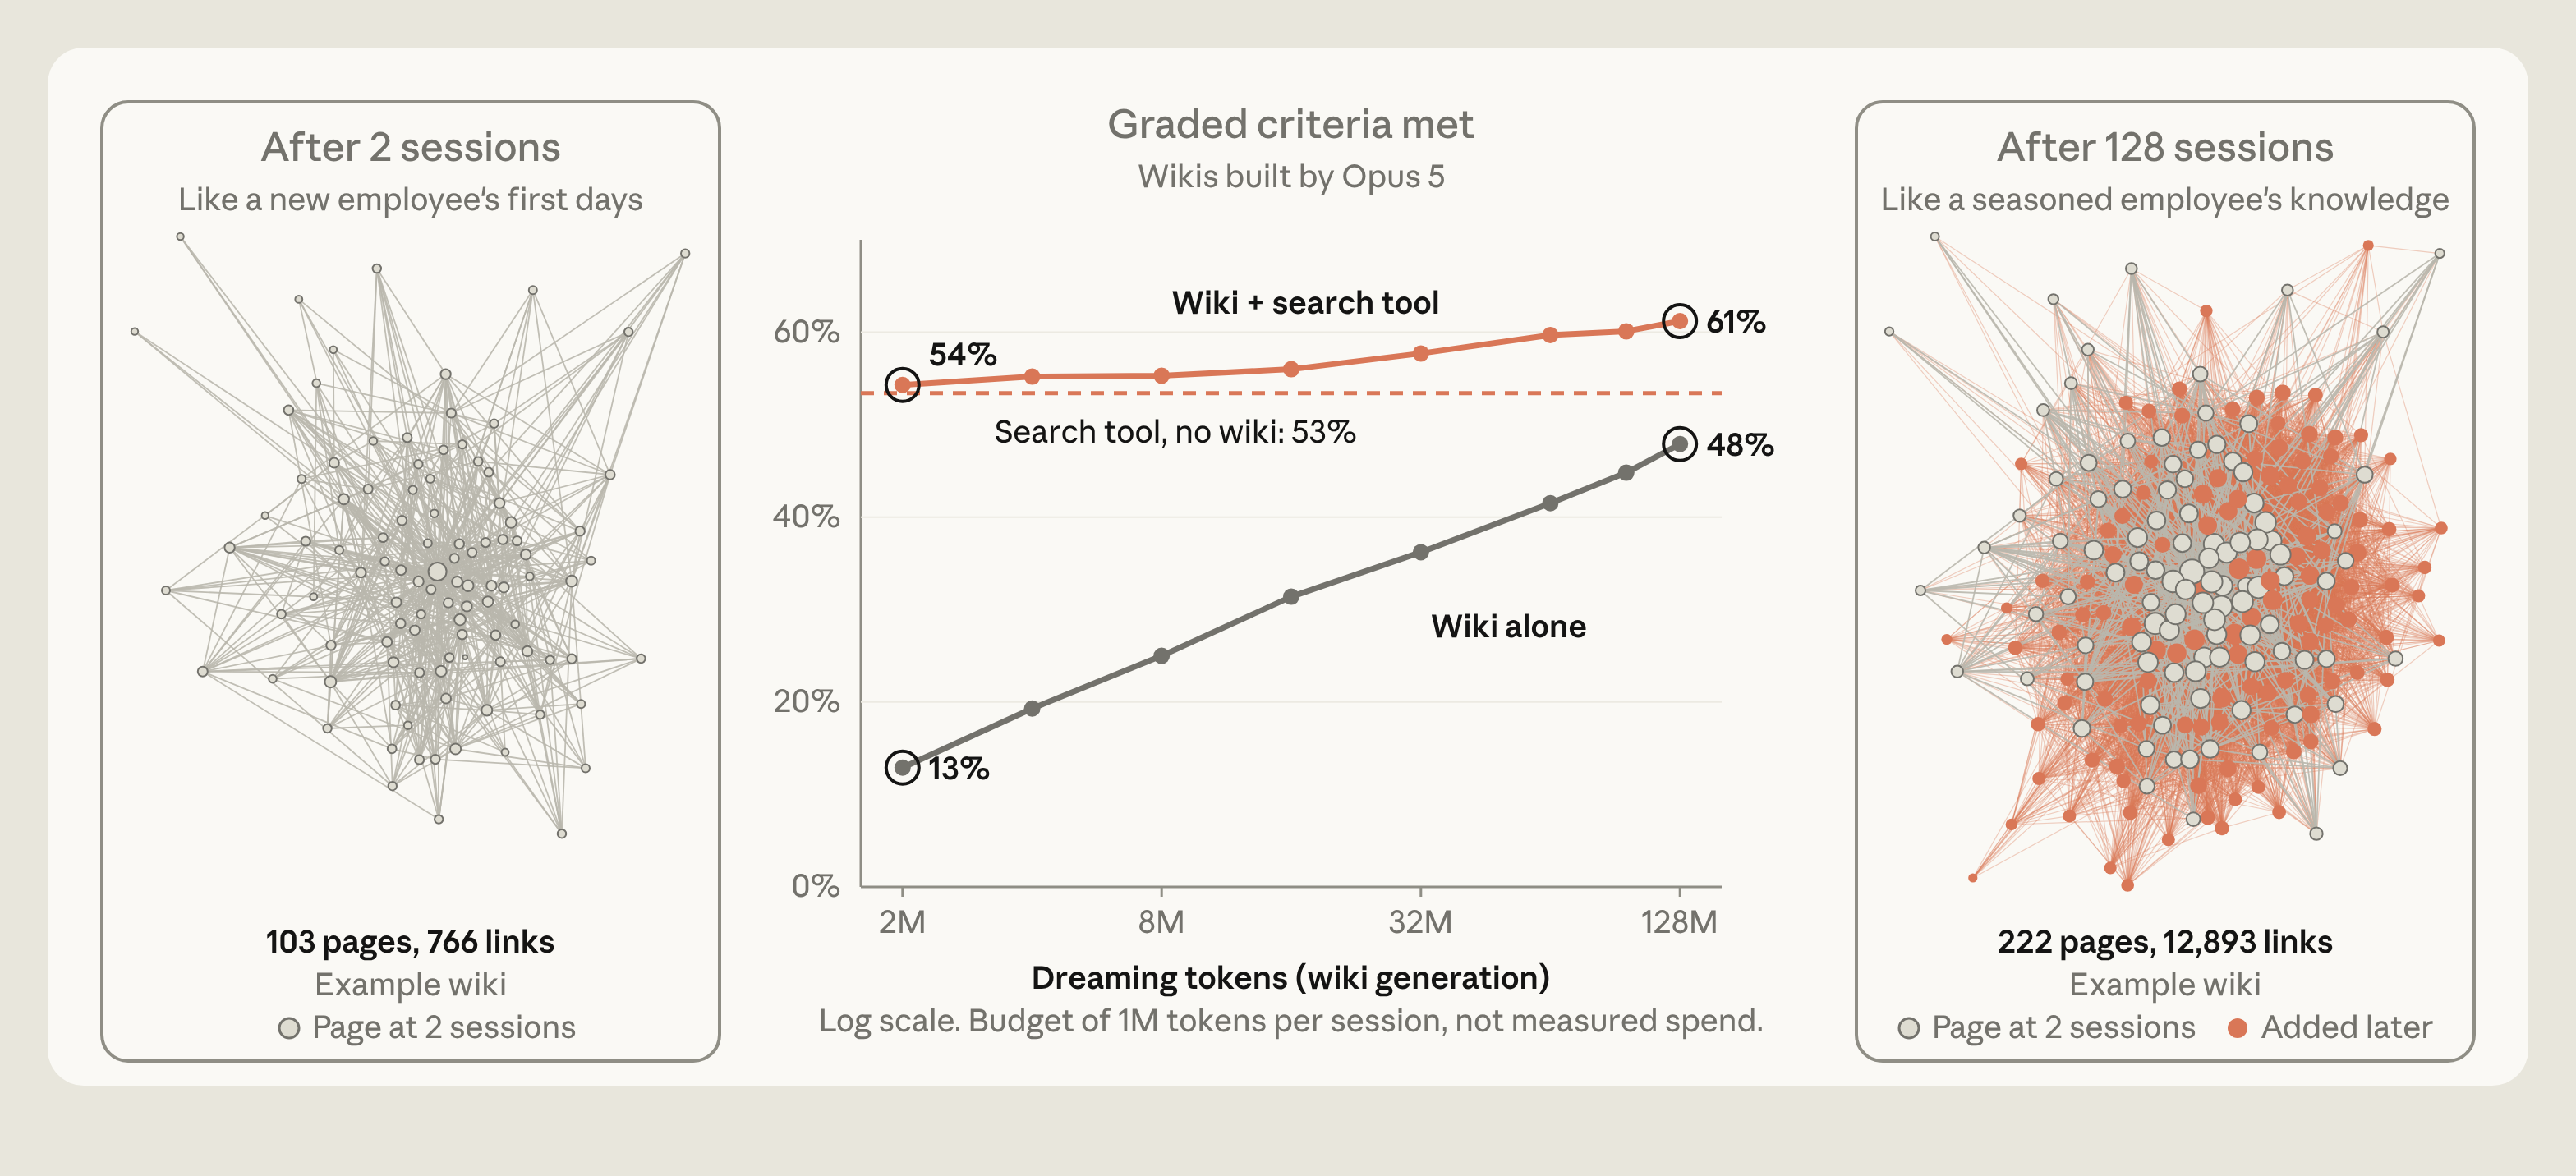
从 2 个会话增加到 128 个会话后,仅依靠知识库作答时,满足评分标准的比例从 13% 增至 48%。同时提供知识库和搜索工具,分数则从 54% 增至 61%;只有搜索工具时为 53%。两者结合,每题还大约节省 20,000 个词元。
媒体未能载入,请通过下方原文链接查看。
图 10:Dreaming 从约 200 万个词元增加到约 1.28 亿个词元时的评分与知识库变化。示例知识库从 103 个页面、766 条链接,扩展到 222 个页面、12,893 条链接。
知识库的价值也取决于题目。研究者又使用并购文档与 Harvey LAB 法律基准,比较直接搜索和查阅知识库的表现。
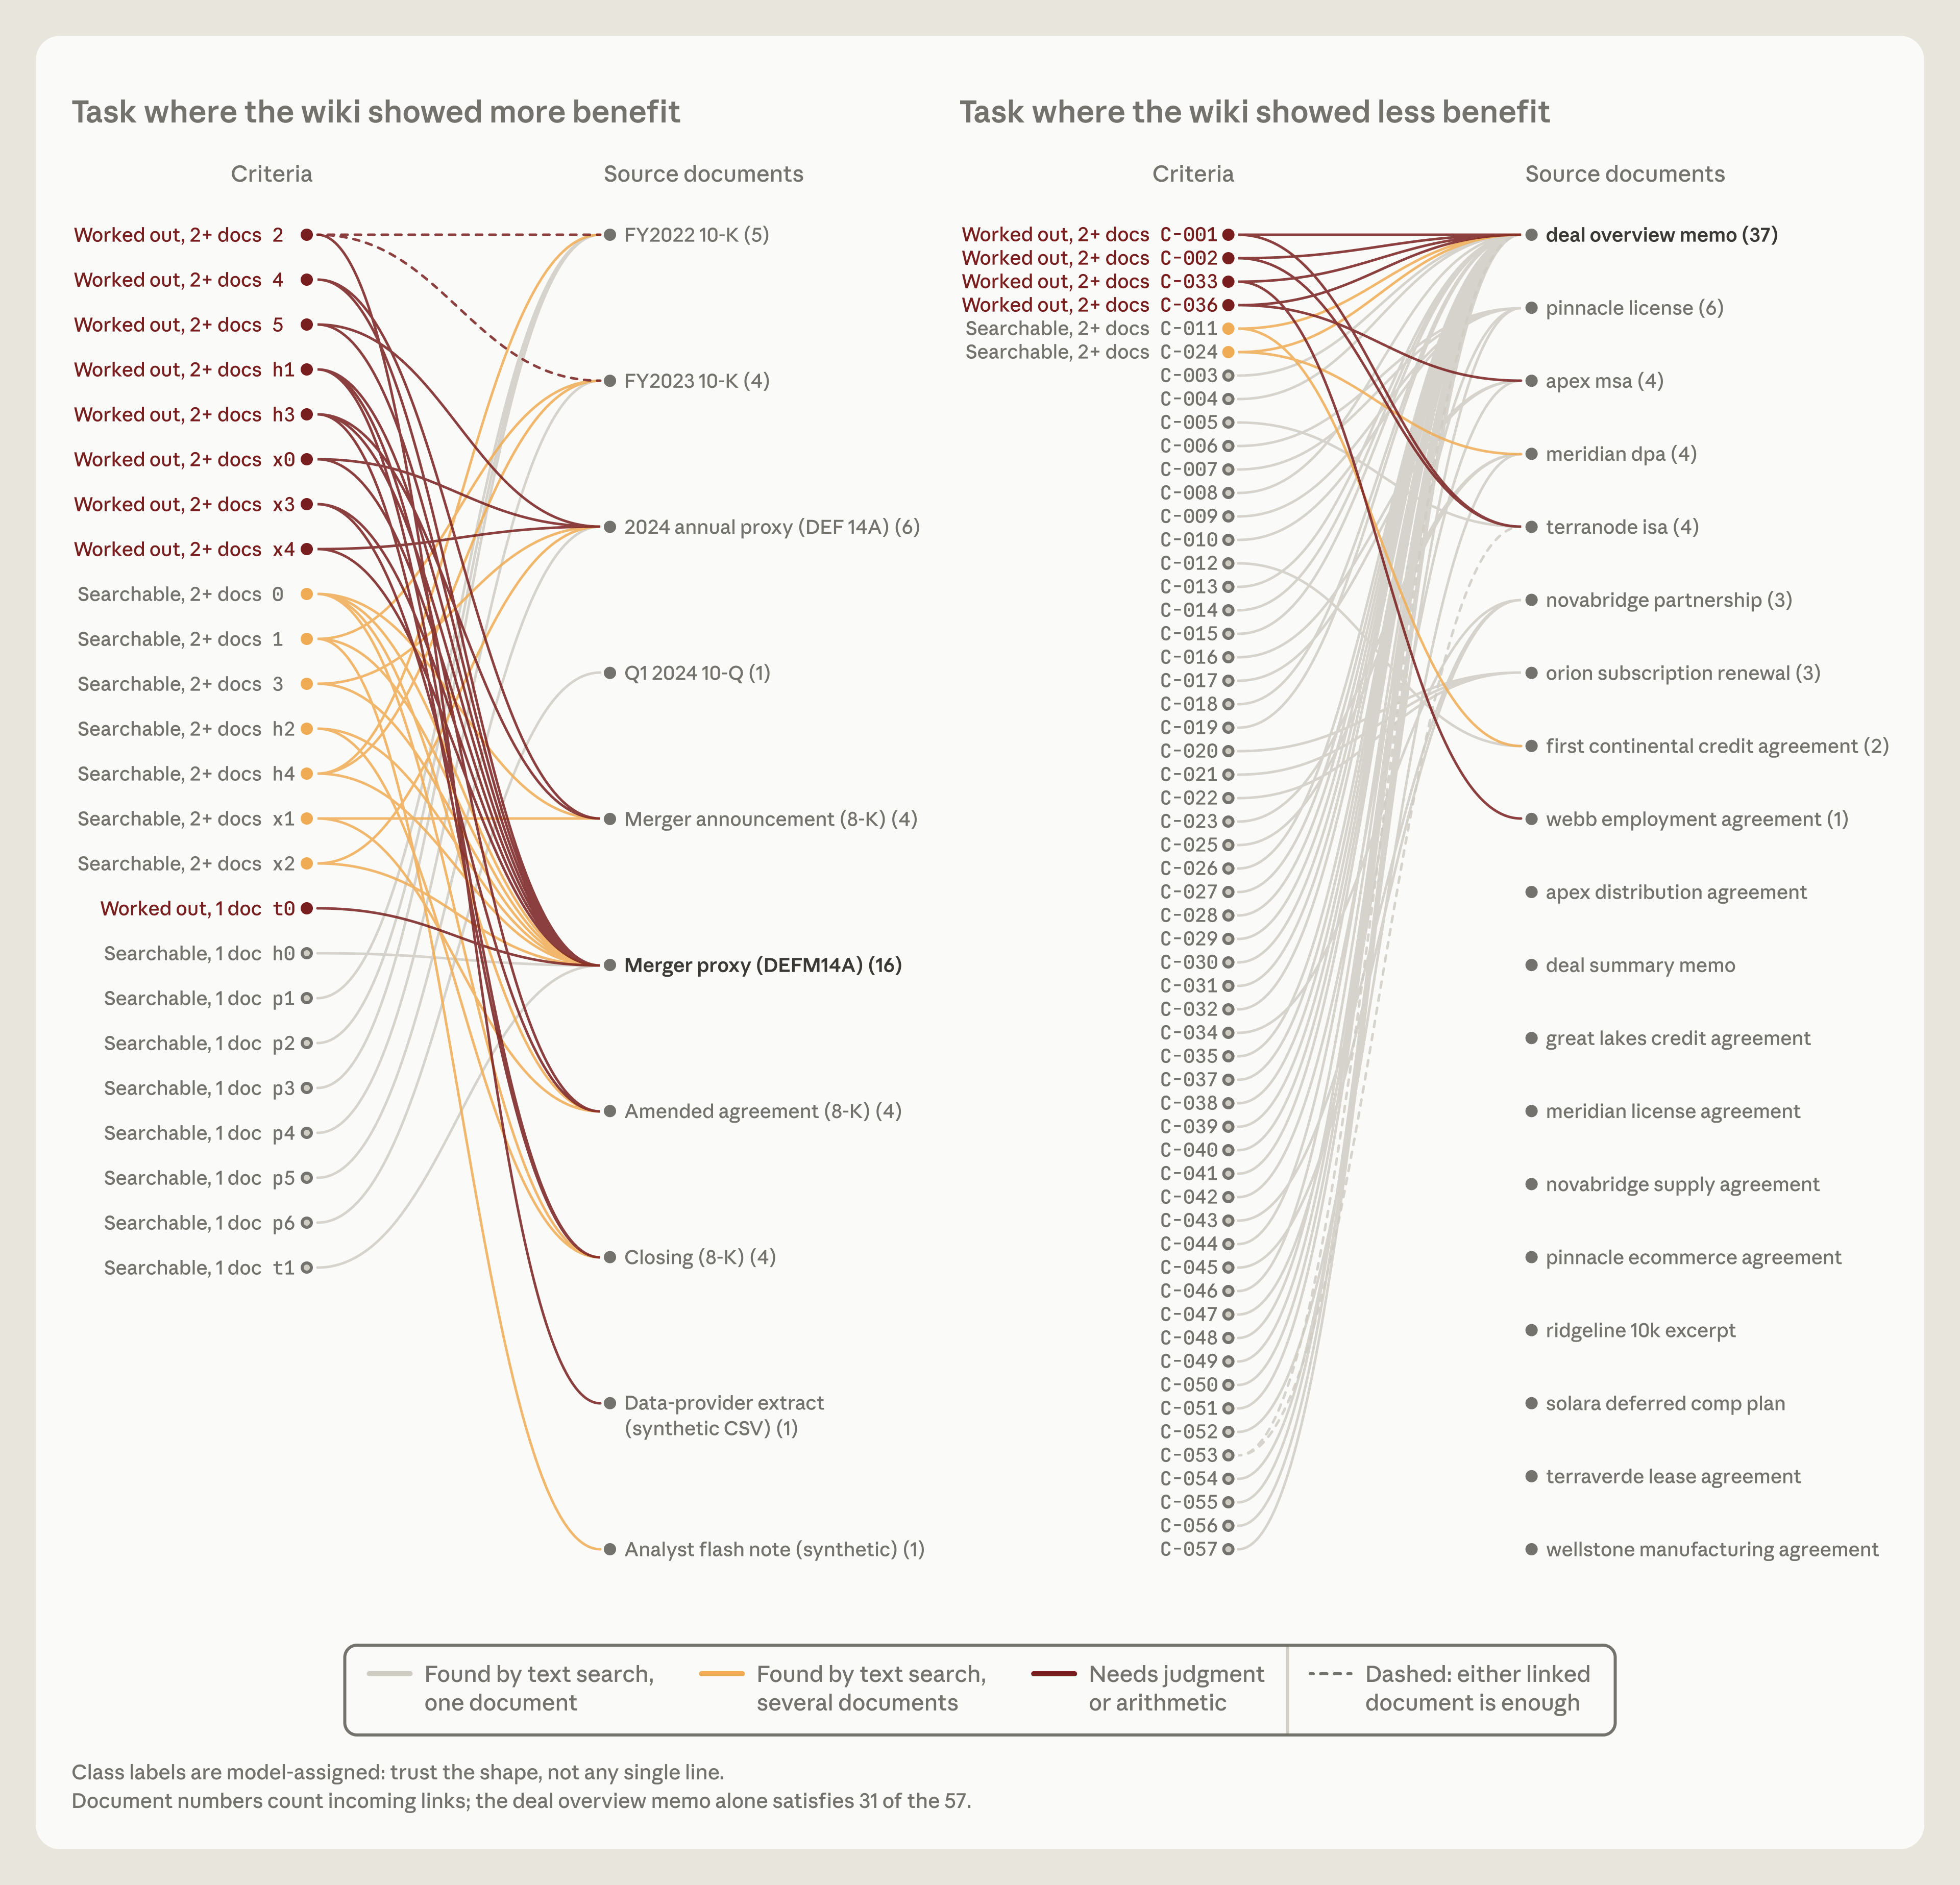
一项并购测试有 24 道题,其中超过一半需要跨文档查找,不少还需要判断或计算。在需要跨文档或额外判断的条目上,查知识库的得分为 87%,只搜索为 73%。
媒体未能载入,请通过下方原文链接查看。
图 11:左侧任务需要跨多份文档组织信息,其中 9 项需要判断或计算;右侧多数要求能从单份文档直接搜索到。
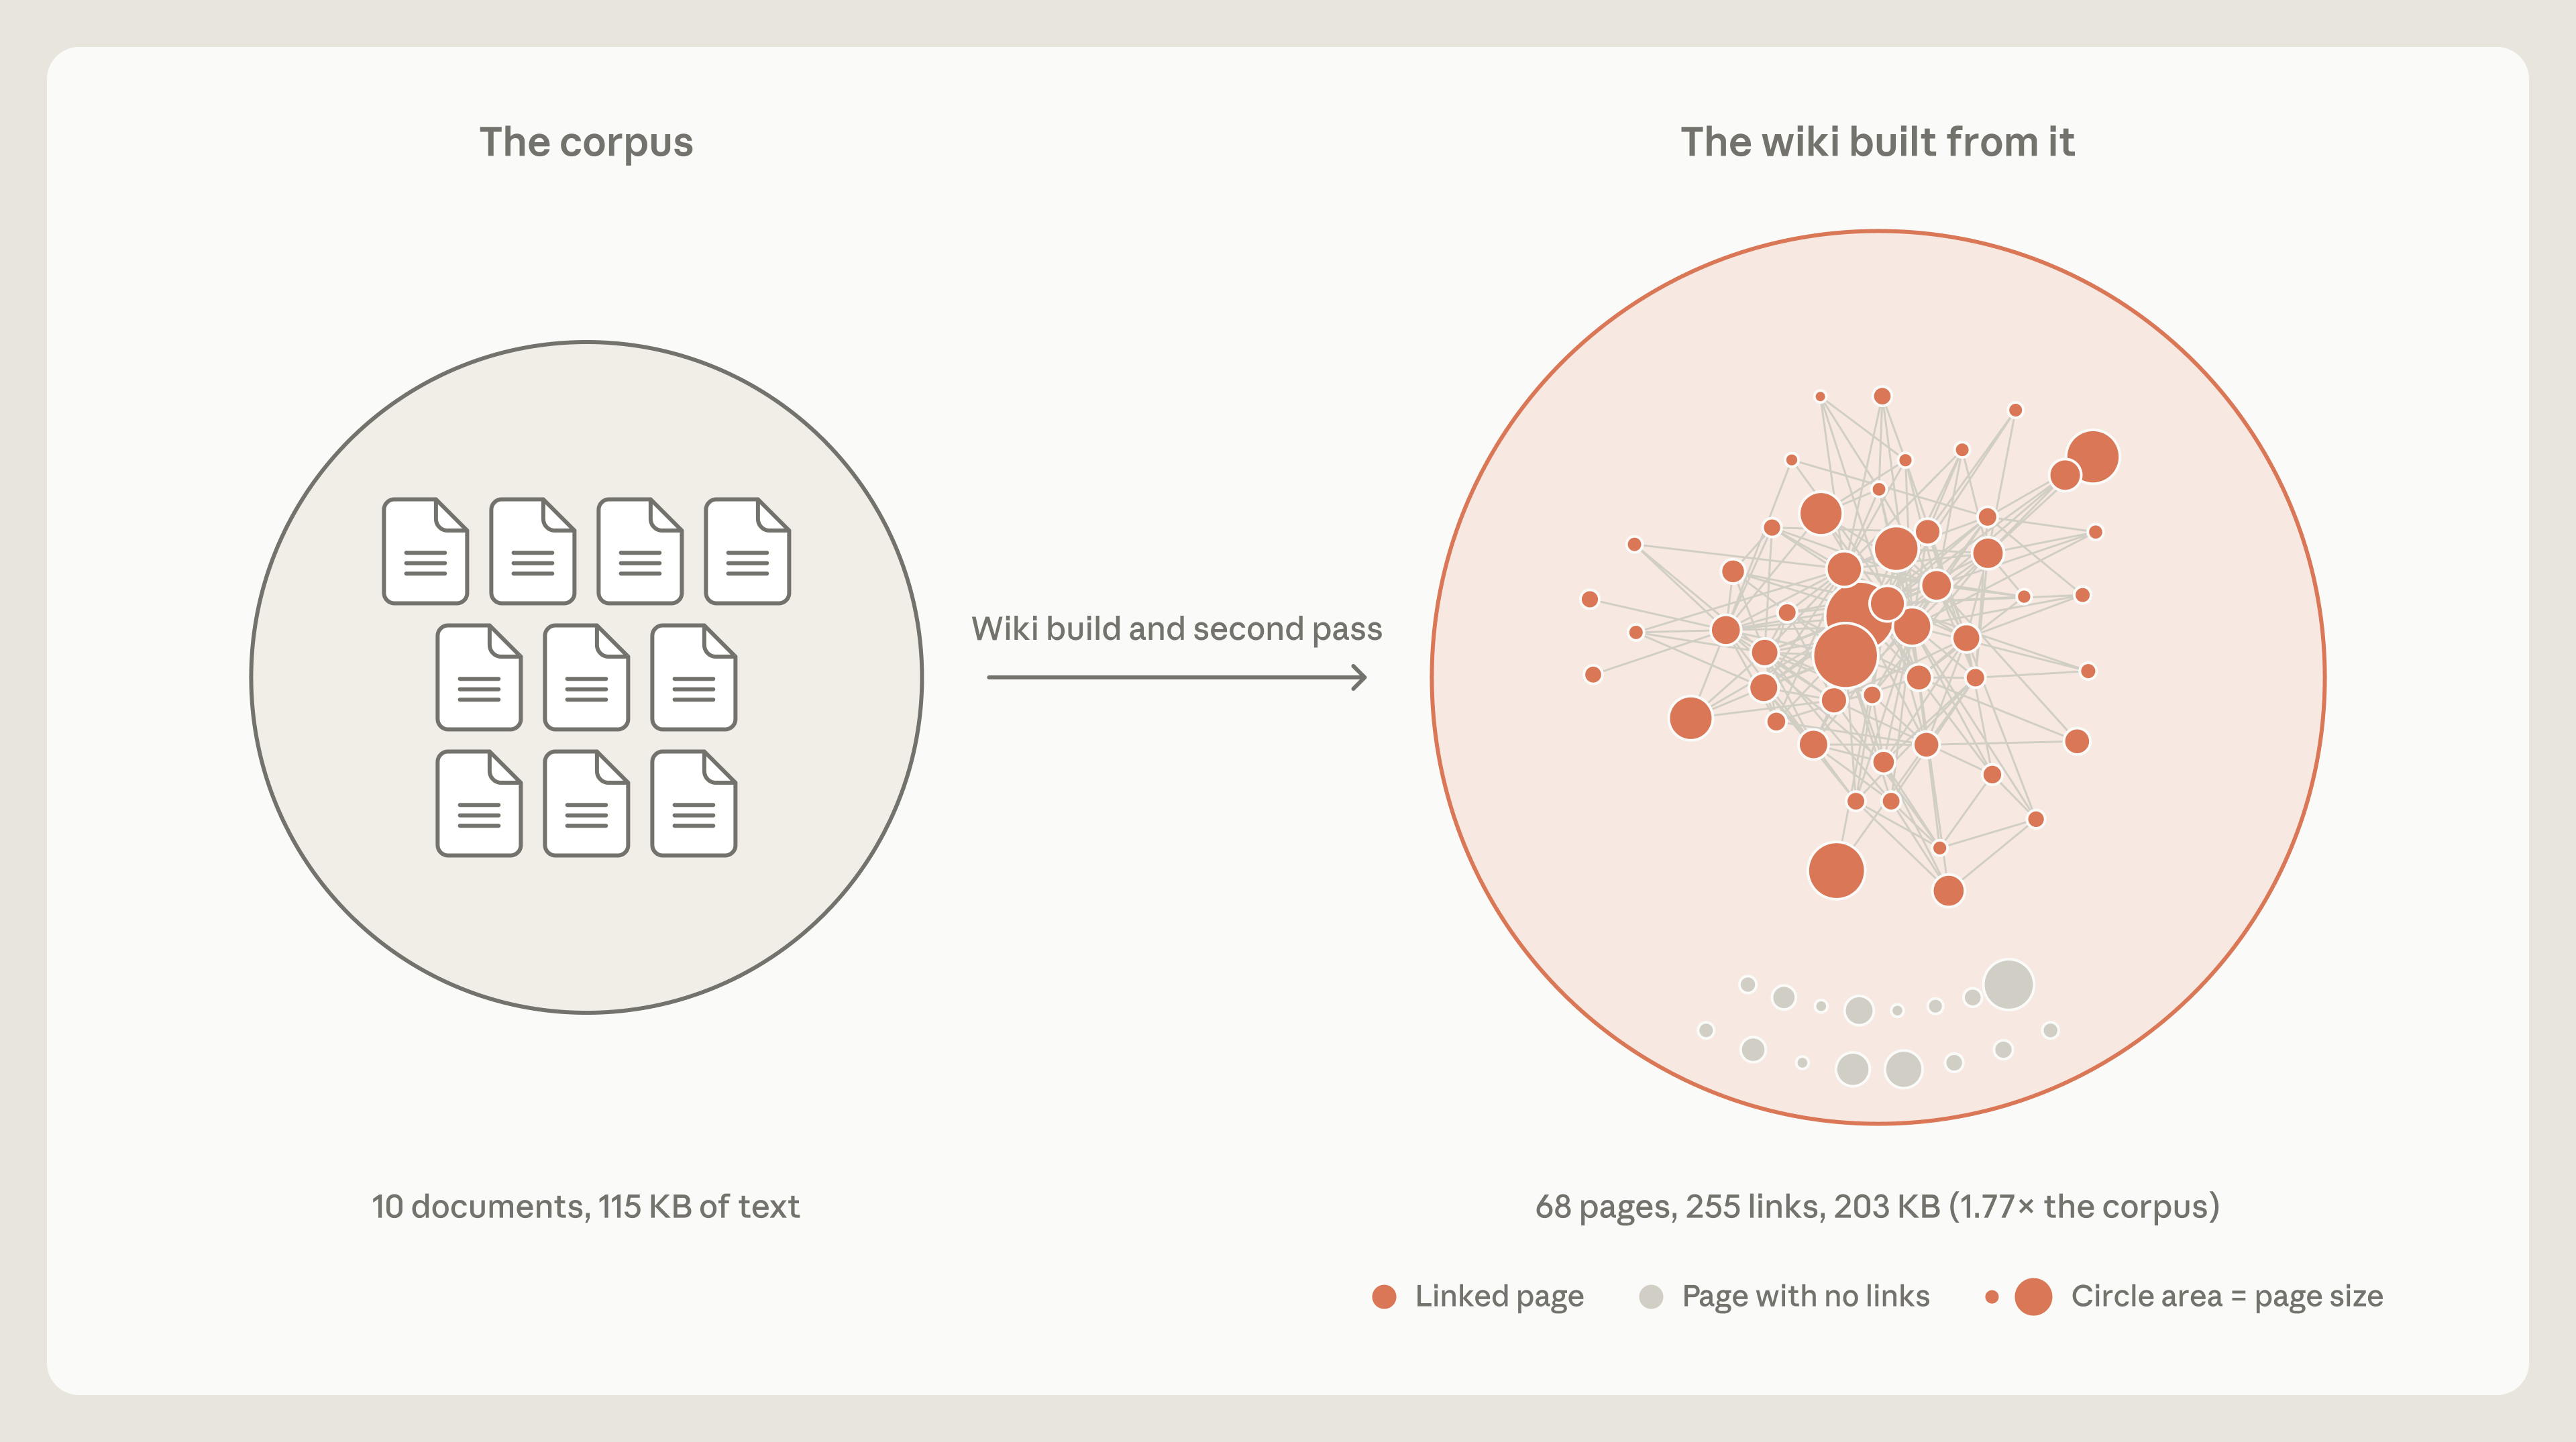
另一个 LAB 任务中,答案常常就在一份文档里,知识库没有带来明显提升。还有一次,10 份文档共 115 KB,Claude 却整理出 203 KB 的知识库,包含 68 个页面、255 条链接,体积达到原文的 1.77 倍,一些页面还没有链接。
媒体未能载入,请通过下方原文链接查看。
图 12:知识库比原始语料还大,却没有完成有效抽象。规模增长本身无法证明整理有效。
作者把它比作博尔赫斯笔下与帝国一样大的地图。若整理后的材料几乎只是重写原文,使用者仍得面对差不多的阅读负担。
每次开场先读的记忆,应该保持小而清楚
Dreaming 也可以挑出少量内容,在每次新会话开始时预先载入。Claude 无须先搜索,也能知道有哪些经验值得留意。
但这层内容会占用上下文。若混进错误,每次新会话都会重新读到。指令越长,也不代表模型越听话,Claude Code 文档明确提醒,较长的指令文件会降低遵从度。
因此,这一层需要保持精简:详细内容下沉到具体文件,入口只留下必要说明与链接。
Claude Code 的自动记忆采用类似安排。每次会话只载入 MEMORY.md 的前 200 行或 25 KB,用它作为索引,说明哪些信息已经保存、该去哪里找。这层索引由 Claude 在会话中维护,自动记忆的全部内容不会随每次会话一起载入。
媒体未能载入,请通过下方原文链接查看。
图 13:把少量记忆提升为新会话的预载上下文,细节继续保存在下层。
整理合同,先保证条款不会被覆盖
知识库该怎样组织,还得看它最后要完成什么任务。像 Claude Duet 这样的助手,可能需要围绕服务对象组织记忆;合同任务则必须保全具体条款。
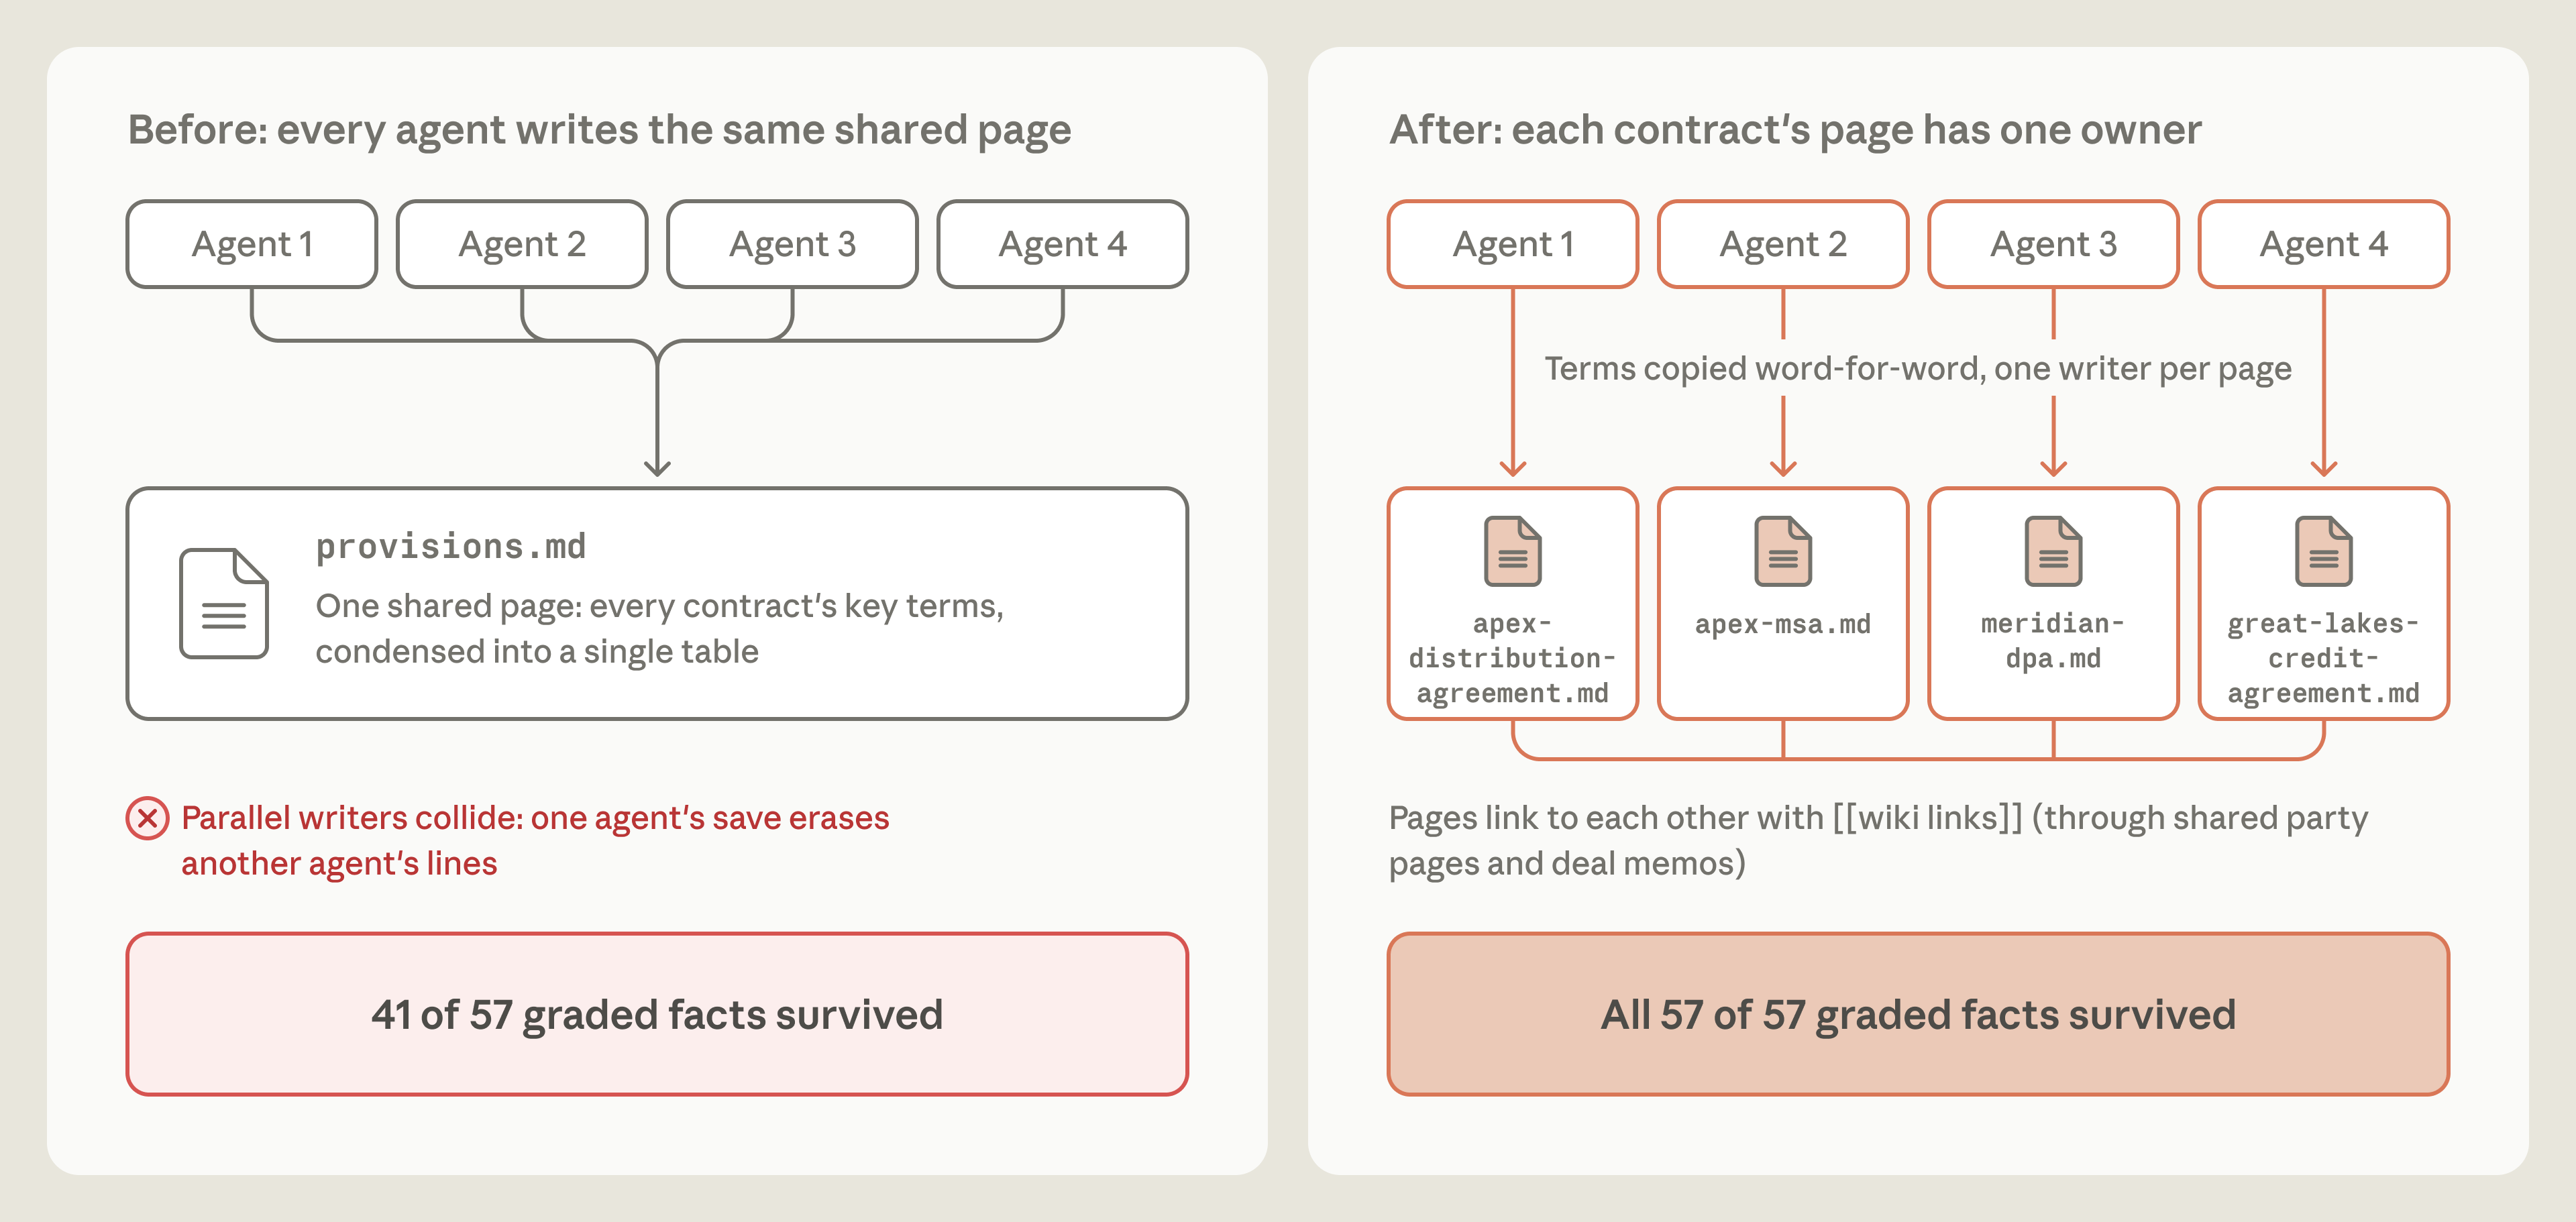
LAB 的一项模拟收购任务中,研究者最初只要求建立知识库,没有说明条款才是评分重点。多个智能体同时往同一张共享条款表里写内容,摘要丢失了细节,部分内容还被彼此覆盖。
用这份知识库生成的简报,只覆盖 57 项事实中的 41 项,约为 72%。
研究者让 Claude 回顾失败,调整指令,再重新建立知识库。修改后的做法是:每份合同单独成页,由一个智能体负责,逐字引用条款。之后生成的简报满足了全部 57 项评分要求。
媒体未能载入,请通过下方原文链接查看。
图 14:从多个智能体共写一张条款表,改为每份合同独立成页并保留条款原文,覆盖情况从 41/57 提高到 57/57。
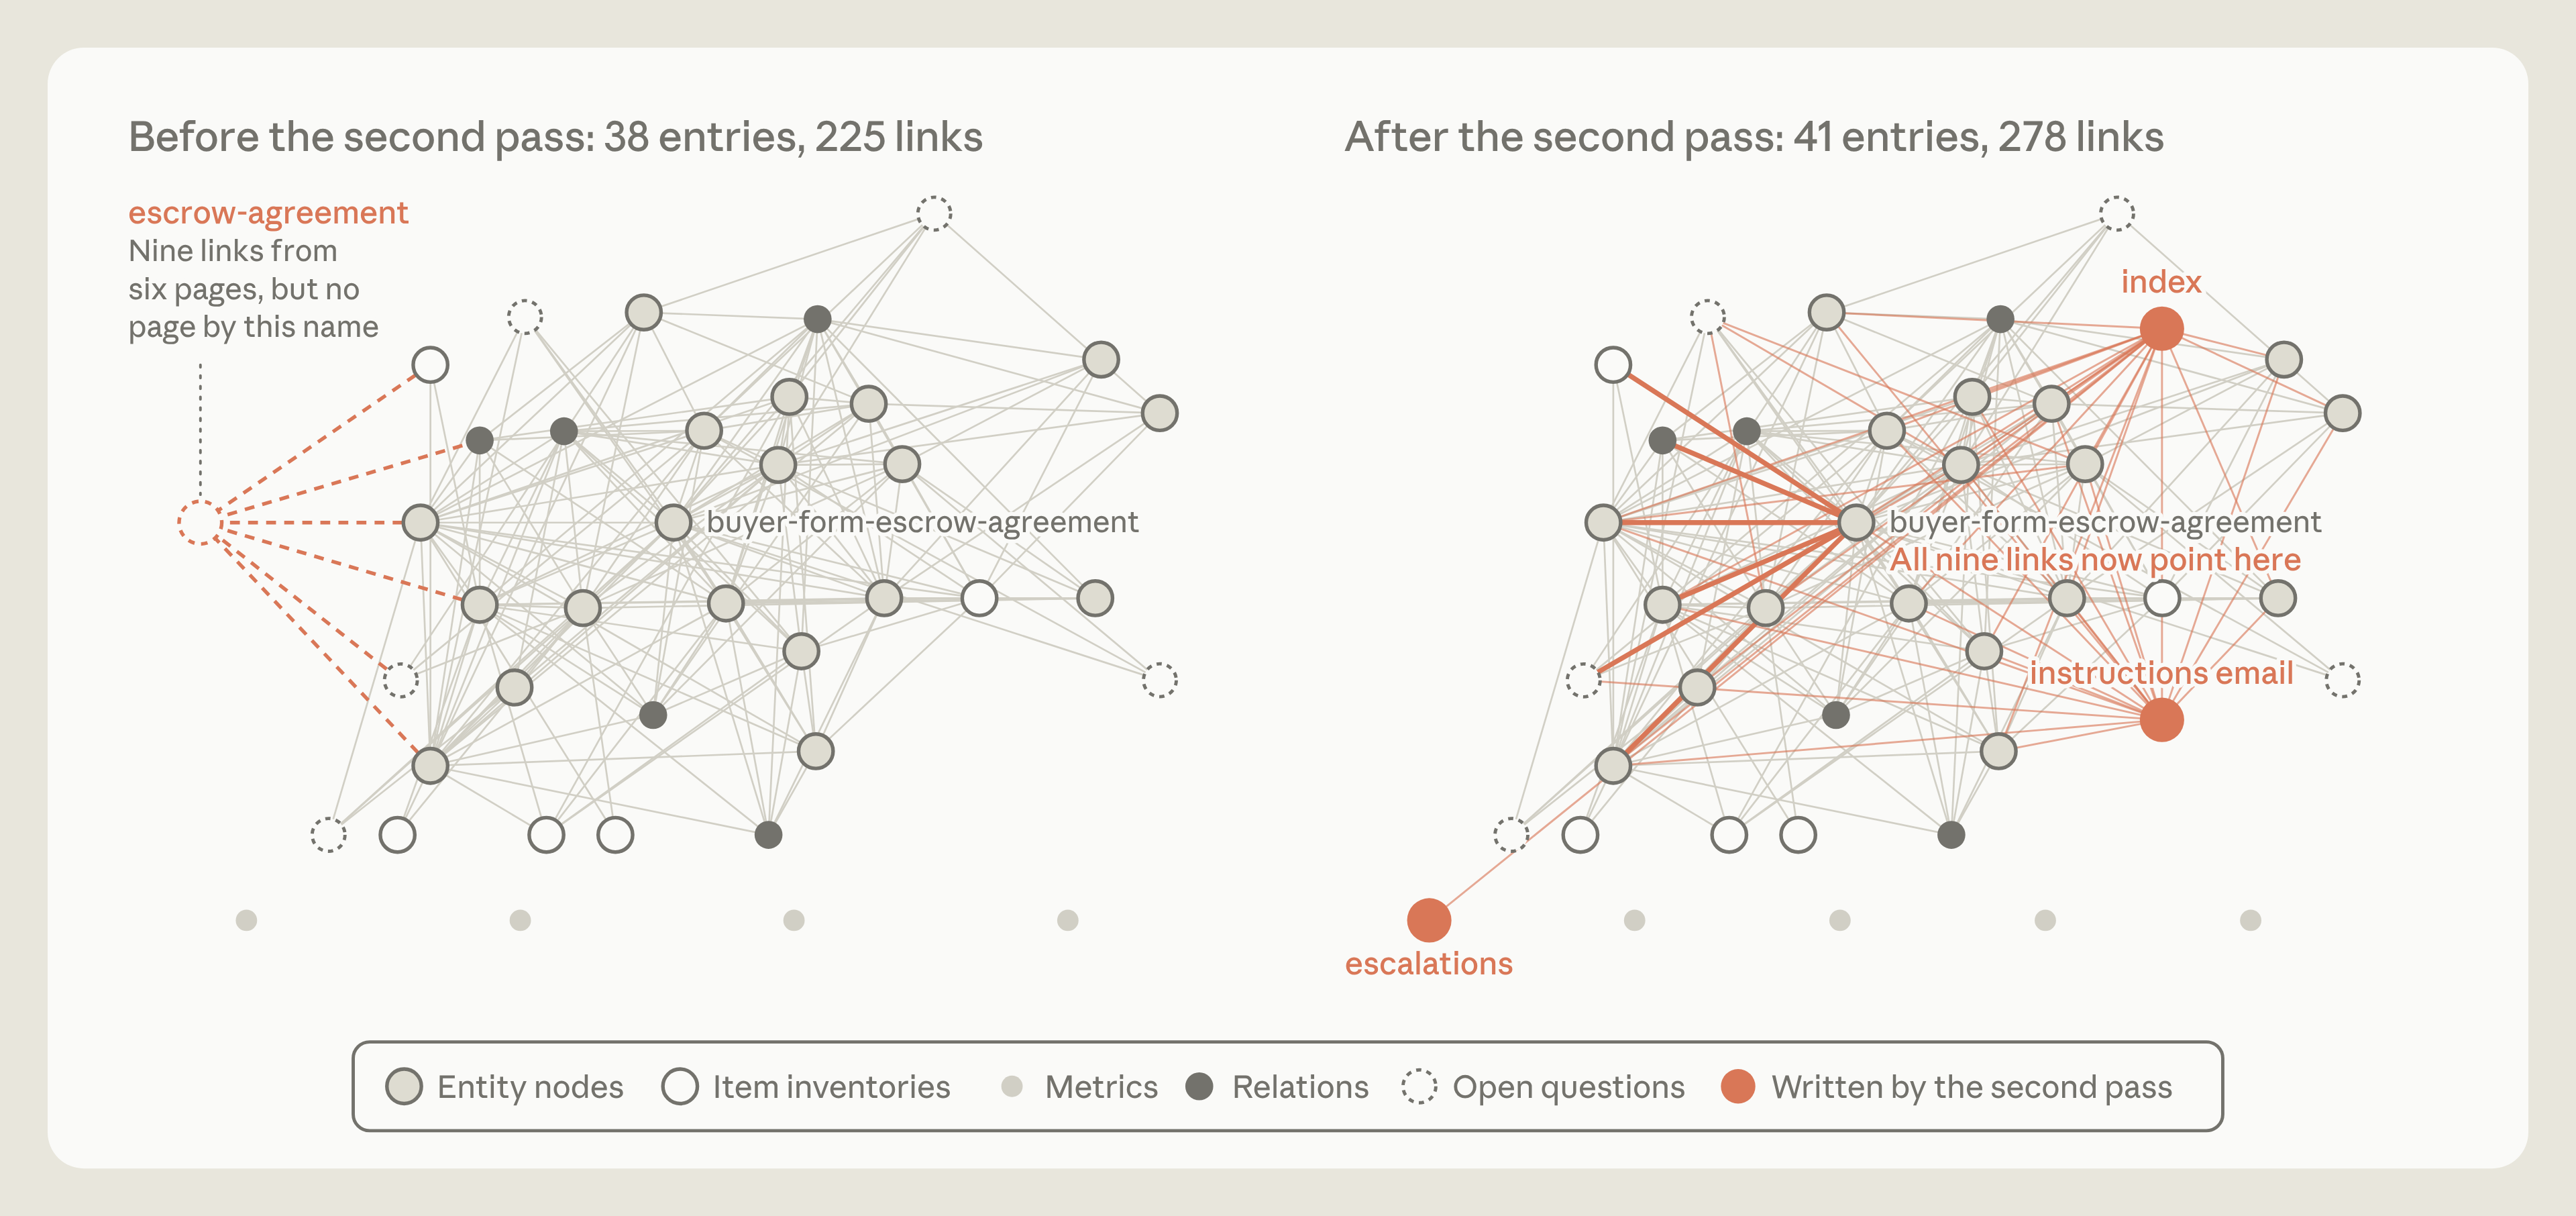
第二轮整理还可以检查跨会话留下的缺口。另一项任务里,6 个页面上的 9 条链接指向一个不存在的页面。Claude 找到同一文档已存在的页面,修正链接,另补上索引等 3 个页面。
媒体未能载入,请通过下方原文链接查看。
图 15:第二轮整理前后,页面数从 38 增至 41,链接从 225 增至 278;原有的 9 条断链从不存在的 escrow-agreement 改指向已有的 buyer-form-escrow-agreement,并补上索引、指令邮件和升级处理页面。
先查记忆有没有被用对,再决定要不要多记
这些实验仍留下不少问题。当场写记忆,重要信息能立即供后续使用,但会分走任务注意力;后台整理能减少打断,结果却未必来得及用于当前工作。
纠错也需要算力。反复检查全部记忆未必可行,研究者提出,可以优先关注容易变化的信息,或根据记忆被读取的频率调整整理节奏。会话记录搜索仍可作为基础,知识库等整理层要持续维护,避免积累错误与幻觉。
这篇研究没有给出适用于所有任务的固定配置。没有模型能预知后续会话会遇到什么。原文给出的实验,更适合转化成几个检查问题:记忆是否被读取,规则是否验证过,笔记是否已经过期,索引能否带到原始依据。
若智能体正在反复犯同一个错误,先回看它读到的笔记,再考虑扩充记忆。若任务用搜索就能完成,先比较增加知识库带来的收益和维护成本。需要优化的,是下一次任务能否更可靠地完成。
原文:The components of agent memory。作者为 Lance Martin,配图为 Monika Tuchowska。本文数据与案例均来自该文,实验结果仅对应文中所述设置。
原文
The components of agent memory
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
The components of agent memory
Published Nov 6, 2026 · Team: Engineering
Written by Lance Martin with editorial guidance from Caitlin Love, Tom Chivers, Rebecca Hiscott, Jake Eaton, and Blake Wilson. (Full acknowledgements at end.)
Søren Kierkegaard wrote that life can only be understood backward, but it must be lived forward. We've encountered a similar bind when designing memory for AI agents.
As humans, we encode memory constantly as we go about our lives. The hippocampus plays a central role in this, capturing experiences in the moment so that memories form quickly and are immediately available. But only some experiences are consolidated into long-term knowledge.
Much of that consolidation appears to happen when our brains are offline. As we sleep, and during quiet rest, the hippocampus replays our recent experiences. This is thought to gradually distill those experiences and integrate them into the neocortex—the part of our brains that stores most of what we think of as knowledge.
Agent memory can use a similar division of labor. Agents capture much of their work in logs or transcripts. Researchers at Letta and UC Berkeley proposed sleep-time compute as a way for models to use idle time between interactions to reorganize their existing context. The same idea can help agents organize their memory by reflecting on logs to fix mistakes or produce new notes and representations. This process is often called dreaming (Figure 1).
We've found that dreaming has been a useful tool for helping us give Claude effective memory. In this post, we share how we've come to think about agent memory and walk through several evaluations we've used to explore agent memory, including the use of dreaming, and what each component contributes to memory organization.
Claude can use dreaming to organize memory. This can correct mistakes, create notes, build new memory representations, or shape what's preemptively loaded into future sessions.
Memory notes
By "agent memory," we mean knowledge that Claude gains from experience—including interactions with users and tasks it's been assigned—and that it retains between sessions, saved as context it can read later. It excludes other ways models can learn or manage context, such as changes to their weights (the internal parameters set during training), in-context learning (knowledge gained within a single conversation), and compaction (summaries written by Claude that replace its older turns so it can continue working in a new context window).
In the human brain, chemical signals released before, during, or after an experience can mark a memory as important. Marked memories tend to be replayed more often than unmarked ones during offline periods. This process, called replay, helps stabilize and integrate them into long-term memory.
Similarly, Claude can tag salient events in a session log as they happen, so they're easier to find later, or it can write them to a memory store, such as a folder of memory notes (Figure 2). But how can Claude tell what's salient in the moment, before it knows what's coming next?
Claude can write notes to memory.
Memory can be a prediction about what the future will need
Memory is, occasionally, a prediction. By writing down a rule, an agent predicts that the pattern it's describing will be relevant again. For instance, writing down a verified fact is a prediction that an agent in a future session will want to rely on that fact without double-checking it. Over time, Claude has become much better at making these kinds of predictions.
Consider a task from Continual Learning Bench (CL-Bench) 1.0, a benchmark that measures an agent's ability to use memory in order to tackle long-horizon tasks. One particular task asks Claude to answer a series of questions by looking up information in a database. After Claude gives an answer, it's told the correct solution and can write a memory to help answer future questions.
Memory can support a learning loop here. If Claude gets a question wrong, it can record the failure, come up with theories about what went wrong, test those theories, and turn what it finds into a rule about how to answer in the future.
We ran the CL-Bench 1.0 task using Claude Managed Agents. Claude started each question in a fresh session, with one exception: it could retrieve files from a memory directory that persisted from one session to the next.
Different models achieved different levels of success at creating their own learning loops. Claude Sonnet 4.6 got as far as generating theories about why an answer was wrong. Its memory directory contained a scattering of files, each listing several untested guesses.
Claude Opus 4.7 consolidated its notes into a single reference document and began marking which facts it had checked and which were still unconfirmed. Claude Sonnet 5 marked each answer as confirmed after the grader had checked it, and wrote a correction when it had answered wrong.
Claude Opus 5 was the first of these models to close the loop. Most of its entries included a rule (and also how it knew the rule was true), answers to earlier questions, and clear warnings about traps it had discovered along the way (Figure 3).
Like Opus 5, Claude Opus 5.5 and Claude Sonnet 5.5 both closed the loop, using memory to capture validated rules about how to best answer future questions. With memory, both scored about the same as Opus 5, though their baseline performance without memory was slightly higher.
Claude has learned to judge salience
We also evaluated Claude's ability to play Pokémon Red, a game that challenges Claude to navigate complex long-horizon tasks, as a test of Claude's judgment about what to save to memory. At the start of each run, we gave each model a folder of memory files that it could read from and write to while it played (Figure 4).
We compared the memory folders from one run each of Claude Sonnet 3.7 and Claude Fable 5, when each was about 10,000 steps into the game. A key difference we noticed was what each model thought was worth remembering. Sonnet 3.7 assumed everything might matter and wrote to memory indiscriminately. Its memory folder contained an archive of encounters, often with a separate file for each battle it fought, each item it found, and each non-player character it met. Ultimately, Sonnet 3.7 wrote 413 memory files across 225 folders and earned one badge (badges mark a player's progress through the game).
Fable 5, by comparison, wrote nine files in two folders, plus a single top-level file called global.md, and earned four badges.
Sonnet 3.7's approach was a problem mainly because the game state of Pokémon changes constantly—Sonnet 3.7's detailed record was continuously going out of date. As a result, as Claude progressed, it had to spend more time and resources combing through its memories rather than playing the game. Around step 10,000, for example, Sonnet 3.7 started its fourth folder of "master" memory files. Over the next 17 steps, it created six files, deleted nine others, and took no actions in the game itself.
Fable 5's approach used memory for things the game didn't explicitly tell it. Some of the kinds of information Sonnet 3.7 wrote to memory—such as how much money the player has or where the player is on the map—can be read off the screen every turn, so storing it is redundant. By contrast, memory files about strategy, plans, and tested rules exist only if Claude works them out, and they disappear unless Claude writes them down.
Fable 5 organized its memory accordingly. Its global.md file acted as a dashboard, holding the current goal, a prewritten plan for tackling gyms (the challenges where badges are won), and the model's own rules for using memory. A locations folder held plans for navigating particular routes, and a gameplay folder held strategies based on what it had learned about how the game works. For example, after seven Poké Balls in a row failed to catch a Magikarp (one of the easiest Pokémon to catch), Claude wrote, "If 3+ balls fail in a row, VARY the timing (insert extra 'wait' presses between menu steps) - the catch landed right after doing this."
With a much smaller memory folder, Fable 5 progressed much further in the game than Sonnet 3.7. Opus 5.5 took a similar approach: it kept a small folder of memory notes that tracked its current goal and next steps, rewrote them as it played, and beat the game.
Steering Claude to write memory
We've found that it helps to tell Claude what memory is for, but not how to use it. On CL-Bench, we simply told Claude that a memory folder was available. That general guidance was enough for Opus 4.7 and Opus 5 to use memory effectively, and it gave both a noticeable boost in performance (Figure 3).
We also tested giving the models specific rules about what they should write to memory, with one rule per test. We compared how much each model gained from memory with each rule against how much it gained without it. When we set a rule to "record only failures," both Opus 5 and Opus 4.7 lost much of the performance boost that memory gave them (Figure 5, right). For stronger models, giving them freedom to judge salience was more effective than setting fixed rules in advance, and those rules could end up weakening performance.
We also noticed that steering helped older models the most. For instance, Sonnet 4.6 often didn't read files from its memory directory and failed to test its theories about why an answer was wrong.
In this case, prompting Claude to read its memory files before answering—and then to explicitly test its theories—nearly doubled its benchmark score (Figure 5, left). Sonnet 5 does this on its own. Without being prompted to, it read its memory before answering 9 out of 10 times. By comparison, Sonnet 4.6 did this less than half of the time.
With frontier Claude models, we typically give simple guidance to create memory notes when a person asks them to or when something is clearly worth remembering, and we leave that judgment up to Claude.
Dreaming can correct memory
Since Claude writes to memory based on what it judges to be salient in-session, a note that's wrong from the start or that drifts as the environment changes can be read, and trusted, by Claude in a later session.
Dreaming gives Claude a way to test its notes against the original transcripts (Figure 6). We saw a positive example of this when Claude played Pokémon using Managed Agents with a mounted directory for its memories.
In one part of the game, the player has to get through Mt. Moon, a cave system with its entrance on the west side of the map and its exit on the east. Near the entrance is a trap: a one-way ledge that drops the player onto the route they came from, with no clear way to climb back up. Claude was using the PokéCenter, a building at the mountain's entrance, as a landmark, so whether it walked off the ledge depended on which side of the mountain it thought the PokéCenter was on.
At one point, Claude wrote down (incorrectly) that the PokéCenter was on the east side. When it walked out of the PokéCenter, it announced, "Mt Moon is behind me," and updated its notes: "Mt Moon DONE." But Mt. Moon was not behind it. A few actions later, Claude went over the ledge and landed back on the route it had come from (Figure 7). Its navigation tool didn't show the drop, so Claude concluded, "I overshot far west," and that it had been on the correct side all along. It hadn't.
We then tested whether dreaming could help Claude avoid this trap. We ran dreaming on the memory folder that contained the wrong location for the PokéCenter: Claude checked the note against the session transcript, caught its error, and rewrote it. The transcript gave Claude a ground truth to validate its memory against. With the corrected memory note, Claude went straight back into Mt. Moon and eventually reached Cerulean City.
In the run with the uncorrected note, Claude dropped back onto that earlier route three times. After the third failure, Claude seemed to give up, writing, "I'm going to stop rather than keep looping." Our setup's automatic reply instructed it to continue. So it did, all the way back to Pewter City, the town before the mountain, where it hoped to heal and restock. The run ended without Claude ever reaching Cerulean City.
Dreaming can build new memory representations
With dreaming, Claude can build representations to help navigate memory (Figure 9). One type of memory representation it uses is called a wiki, a collection of pages written and maintained by Claude that gathers what Claude knows about one subject and links it to other notes. These links effectively provide Claude with a map it can use to sift through its memory and efficiently locate memories when they're needed.
Representations like wikis can help Claude traverse its ever-growing knowledge base. We explored the benefit of wikis as a memory representation using a corpus of internal documents—about 350,000 files, roughly 420M tokens—from Stainless, a software company we acquired in May. We created an evaluation set of 25 questions about this corpus and gave Claude a search tool to explore it. We also instructed Claude to build a wiki based on these files using dreaming. Over 128 sessions, we prompted Opus 5 agents to explore the files, write or correct linked wiki pages, merge duplicates, and check claims against the sources.
Each session built on the progress that agents made in prior sessions, using a shared log to coordinate work. As we scaled dreaming from two sessions to 128, performance on the 25 questions grew from 13% to 48% of graded criteria (Figure 10).
Claude builds its wikis incrementally. After creating an initial wiki, it uses subsequent rounds of dreaming to add to, edit, or prune it. In the early rounds of dreaming, Claude's knowledge is like that of a new employee, and its ability to answer questions based on the wiki alone is limited. The more it dreams, the richer its knowledge map grows, like that of a seasoned employee. In our tests, we found that the wiki helped Claude the most when we also gave it access to a search tool. When it used both search and the wiki, Claude's aggregate score rose from 54% to 61% as that wiki grew, compared with 53% when it had access to the search tool alone. Claude's best score was 48% when it used only the wiki to answer questions. Using search and the wiki also saved about 20,000 tokens per question.
We wanted to test which kinds of tasks benefited from Claude having a wiki. To do this, we used the Harvey LAB benchmark along with a collection of documents about a merger. The benchmark gives Claude a set of documents and asks Claude to generate a legal brief based on their content. The benchmark then grades the brief against a list of criteria. While a tad less engaging, perhaps, than a Pokémon run, these evaluations give us diverse collections of documents to build wikis from.
We instructed Claude to build a wiki from the documents. We then asked Claude to answer questions (about the merger) or generate legal briefs (the LAB benchmark) both from the wiki and from a direct file search. One test asked 24 questions about the merger (Figure 11, left), more than half of which needed Claude to find information across several documents, and many of which also needed Claude to use judgment or do math. On those items (red and orange lines), Claude scored 87% when it consulted the wiki, compared with 73% when it used search alone.
In other cases, the wiki was less useful. On one LAB task (Figure 11, right), brief criteria often could be retrieved with a text search from a single document, and the wiki showed no clear gain in performance relative to search. On another LAB task, the wiki grew larger than the documents themselves (Figure 12). Like the mapmakers in Borges's one-paragraph short story "On Exactitude in Science," who drafted a map so detailed it was as large as the empire it represented, Claude had made an extremely detailed wiki that effectively abstracted nothing.
Dreaming can promote notes up the memory hierarchy
Dreaming can also float notes to the top of the memory hierarchy, and the agent harness can preemptively load them into Claude's context at the start of every session (Figure 13). This means Claude doesn't need to search for them, or even to know there's something to search for.
Promoting memories into a new session (a form of context injection) must be done carefully. Injected memories use up valuable tokens, and an incorrect note can be carried into every session. Loading a note also doesn't guarantee that Claude acts on it: our documentation on Claude Code warns that longer instruction files reduce adherence. So the top layer of the memory hierarchy has to stay relatively small, and much of dreaming's work here is keeping it that way—by moving some details down the hierarchy and leaving links behind.
Claude Code's auto memory keeps its injected layer small in the same way, with Claude maintaining it during the session. Claude doesn't load all of its auto memory into every session's context window. It loads only the first 200 lines or 25 KB of MEMORY.md. This header serves as an index, which shows Claude what it knows and where to find it.
Dreaming can focus memory on a specific goal
Dreaming can also shape how memory grows. An assistant like Claude Duet, for example, often benefits from having memories that are organized around the person it's helping, and dreaming can be tuned to build memory in service of a particular goal.
The instructions that guide how memory grows differ by task and tell Claude what information actually matters. For example, one task in the LAB benchmark simulates a company acquisition and provides a set of contracts. The brief is graded on whether it correctly describes the contract terms.
We started with basic instructions for generating the wiki that didn't tell Claude how to use the wiki. This task relied heavily on contract terms. While the wiki was being built, several agents wrote to a shared table of contract terms at the same time (Figure 14, left).
The result was a wiki that was missing key facts. When we graded a brief generated from the wiki, Claude had included only 41 of the 57 facts (72%). When we looked at what had gone wrong, we found that the shared table summarized the contract terms poorly and was missing some of them altogether, because agents had overwritten one another's work.
The contract terms were the most important part of the wiki, but the instructions didn't say that. To find better instructions, we ran a loop in which Claude reflected on its failures, proposed a change to the instructions, and rebuilt the wiki. This loop allowed Claude to discover how important it was to follow the contract terms, and it rewrote the instructions for building the wiki accordingly.
Each contract got its own page in the wiki, written by a single agent, which quoted the terms word for word rather than summarizing them into a shared table. When we graded the brief generated from this improved wiki, 100% of the criteria could be met, up from 72%.
Dreaming can fill in gaps a session leaves behind
When Claude writes memory notes, it sees only the context in that particular session. Dreaming can search across many sessions to find common patterns or correct common mistakes.
When building the wikis for the LAB benchmark (as an example, see Figure 14), sometimes Claude would link to pages that hadn't yet been created. A second dreaming pass closed many of these gaps. On one task (Figure 15), dreaming found nine links to a missing page in the wiki and repointed them to an existing page for the same document. It also added three new pages, including an index, to improve the wiki.
Thinking backward, looking forward
There are many open questions about how to design memory systems for agents. One is when Claude should create memory. When Claude works on a task, it can write to a memory store (e.g., a folder, file, or database), capturing salience at the source and making important details immediately available for future turns or sessions. But logging notes in the moment inevitably draws Claude's attention away from its main task. In contrast, dreaming can push memory creation to the background, but any outputs from dreaming may not be immediately accessible to Claude.
Another question is how to keep memory reliably up to date. Claude can make incorrect predictions or write rules to memory that are wrong from the start. Memory can also drift and become irrelevant as the environment changes. Dreaming is one way to fix these mistakes (Figure 8), but it requires compute. Directing Claude to continuously check all its memories might not be practical. It may be important instead to focus dreaming on information that's likely to change or to carefully tune the cadence of dreaming (e.g., based on how often memories are accessed).
It's also reasonable to consider transcript search as the foundation of Claude's memory. Combining representations (e.g., wikis) with search (Figure 10) can sometimes be effective. But Claude needs to use compute to maintain memory representations and make sure they don't accumulate errors or hallucinations.
Even though Claude's judgment about salience has improved, no model can really know what will happen in future turns. Dreaming gives Claude an opportunity to look backward and use compute to organize its memory, correct mistakes, and maintain representations that allow future sessions to access memory more readily. Memory systems will evolve as Claude gets more capable, and we still have a lot to learn about designing Claude's memory systems.
Acknowledgements
Written by Lance Martin with editorial guidance from Caitlin Love, Tom Chivers, Rebecca Hiscott, Jake Eaton, and Blake Wilson. We're grateful to Barry Zhang, Theodora Chu, Daliang Li, Mahesh Murag, Jake Noble, Ravi Trivedi, Tina Vachovsky, Brad Abrams, Henry de Valence, Jeremy Fox, Matt Bell, Allen Li, Chris Gorgolewski, Eugene Yan, Artur Renault, Wei Zhang, and Kevin Chen for helpful discussions and contributions, and to David Hershey for Claude Plays Pokémon. Figures by Monika Tuchowska.